OpsDesk AI
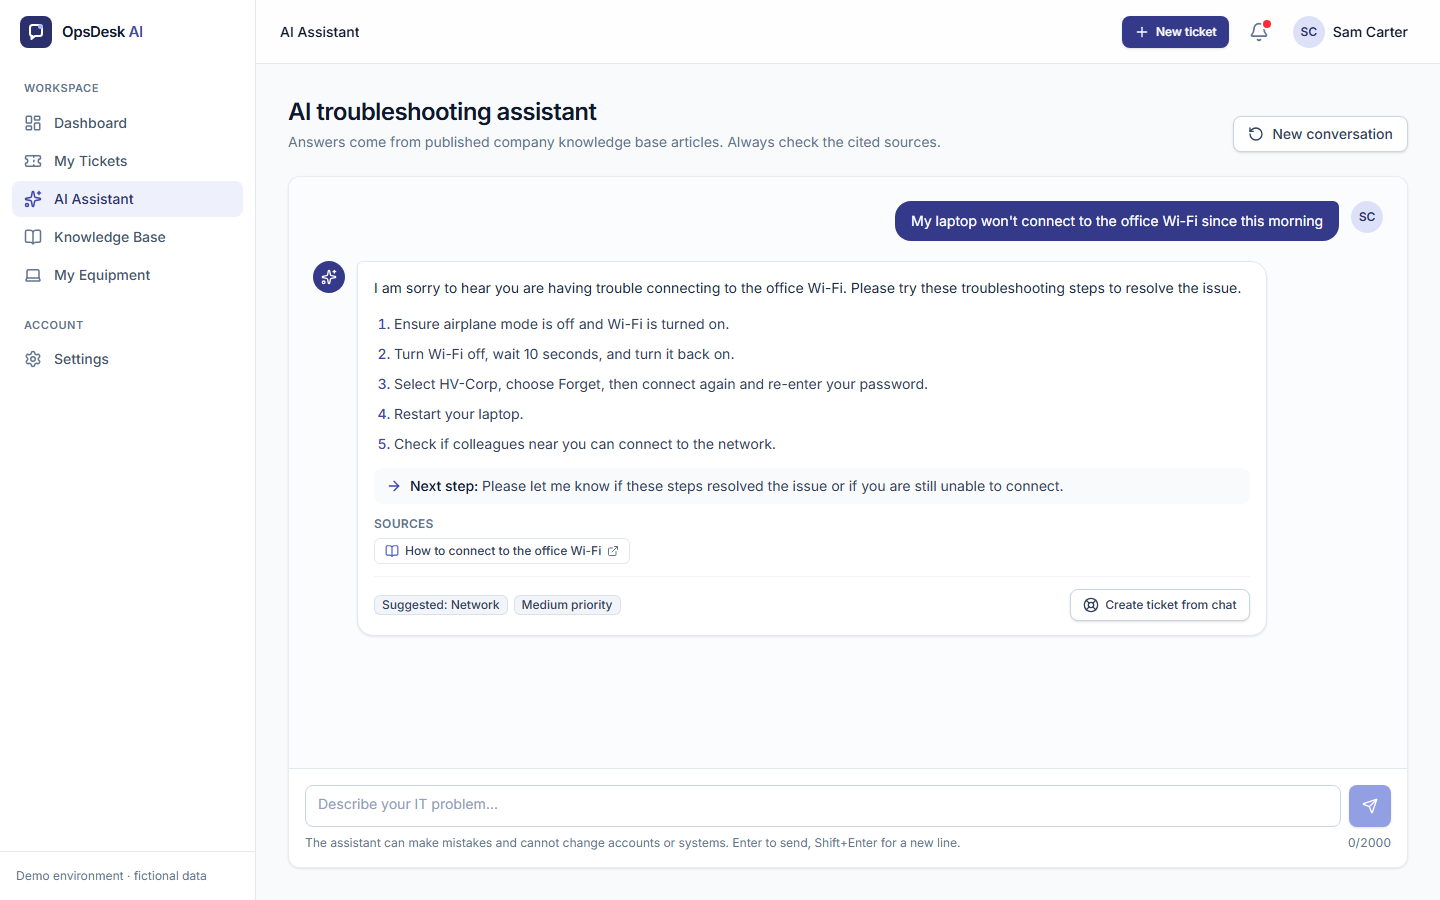
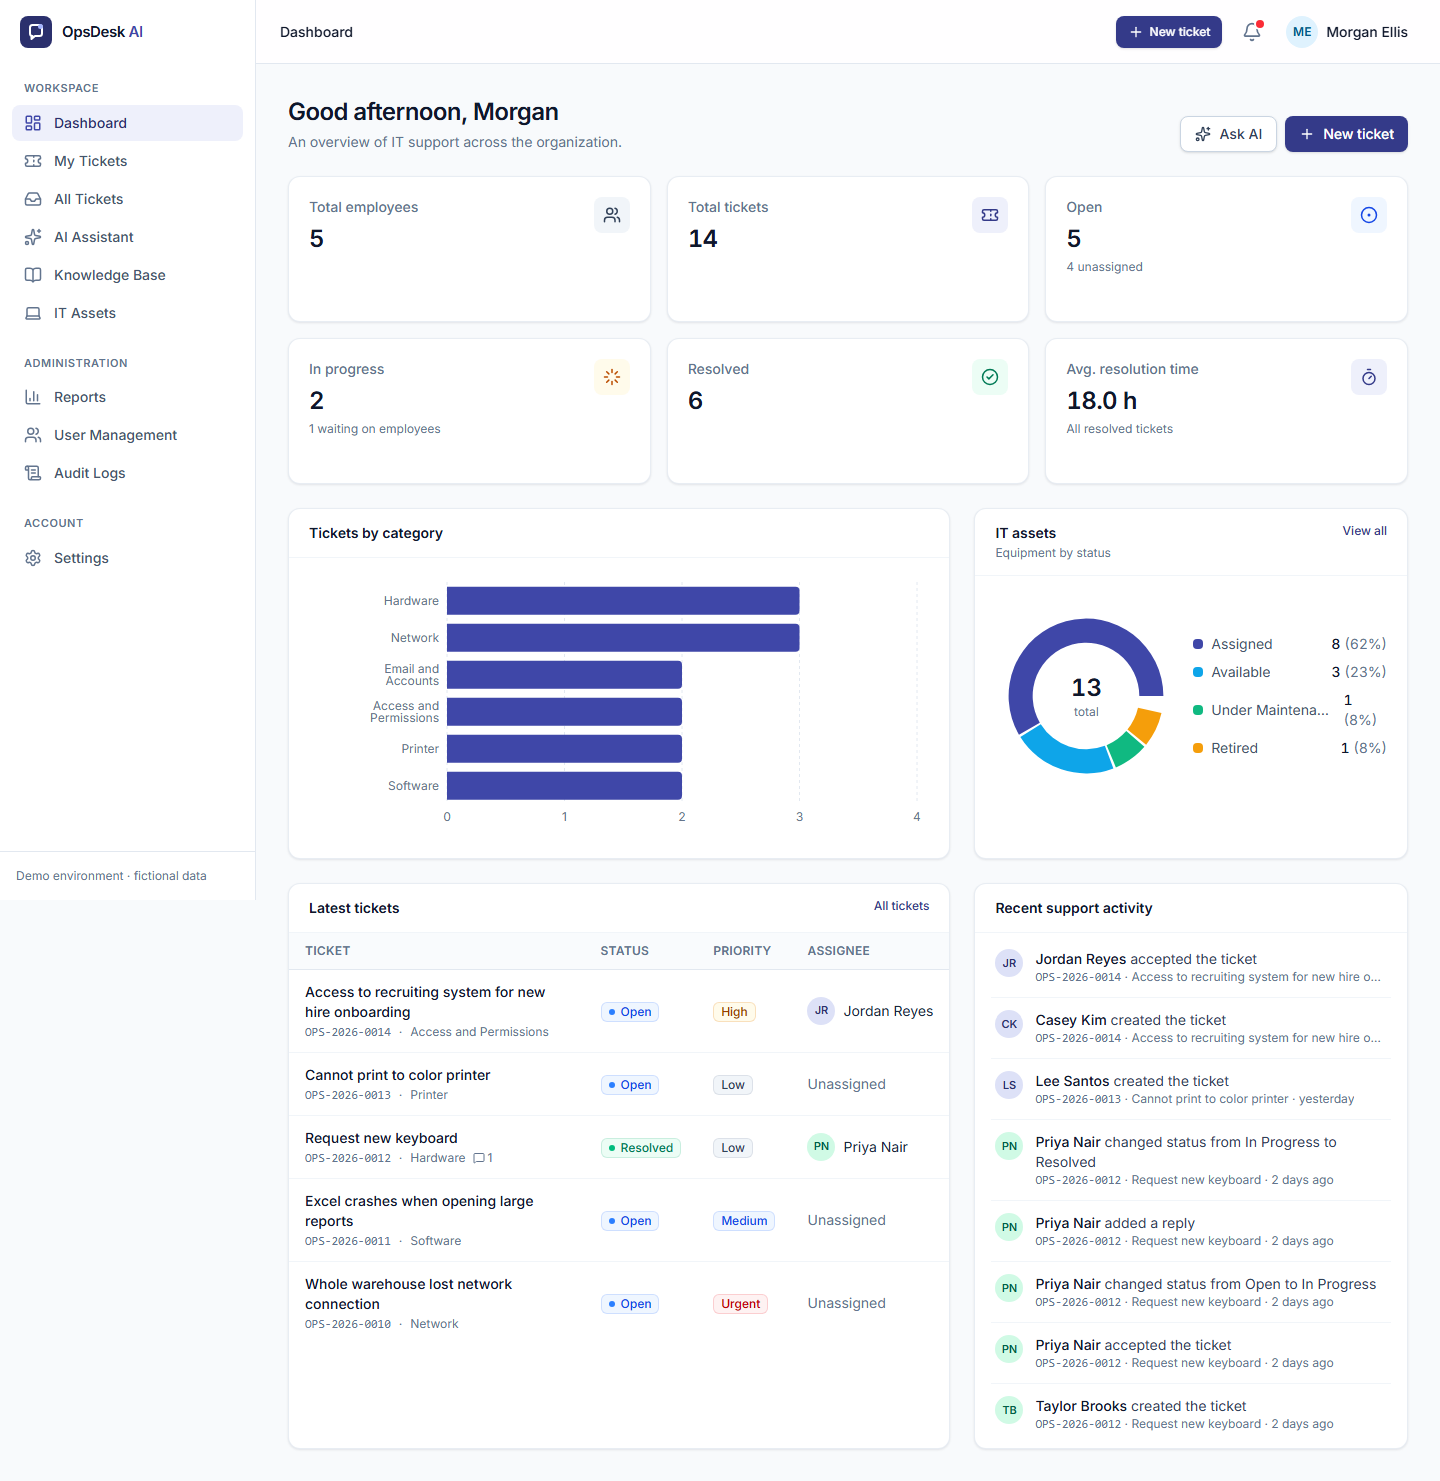
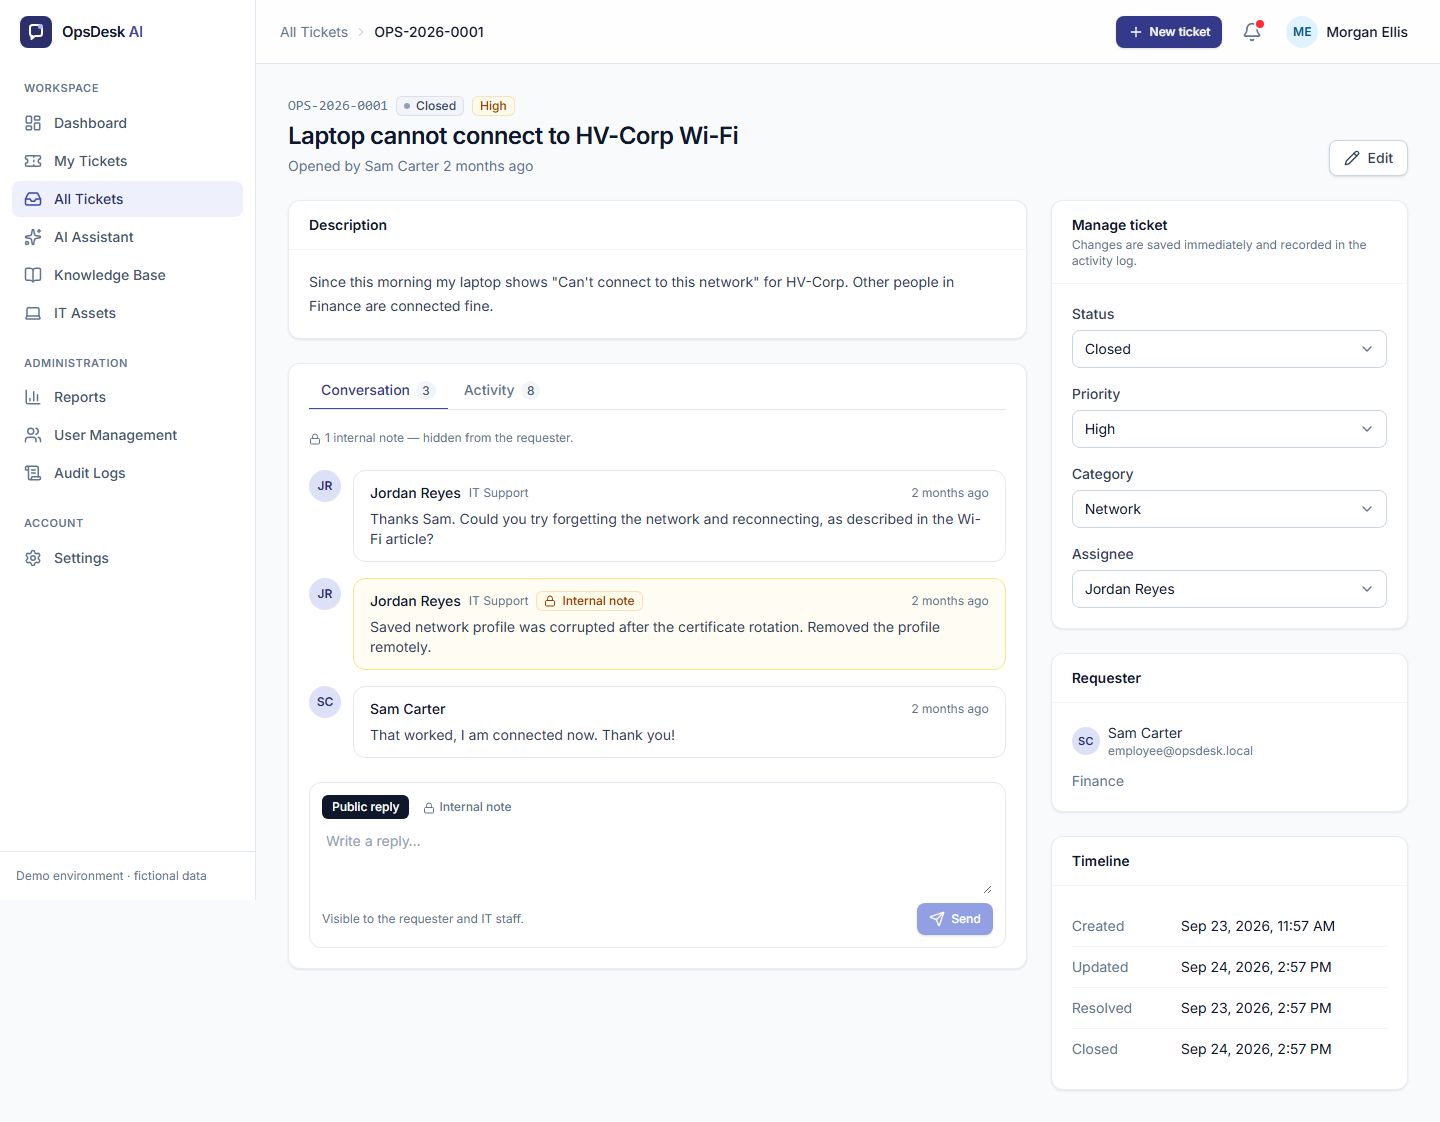
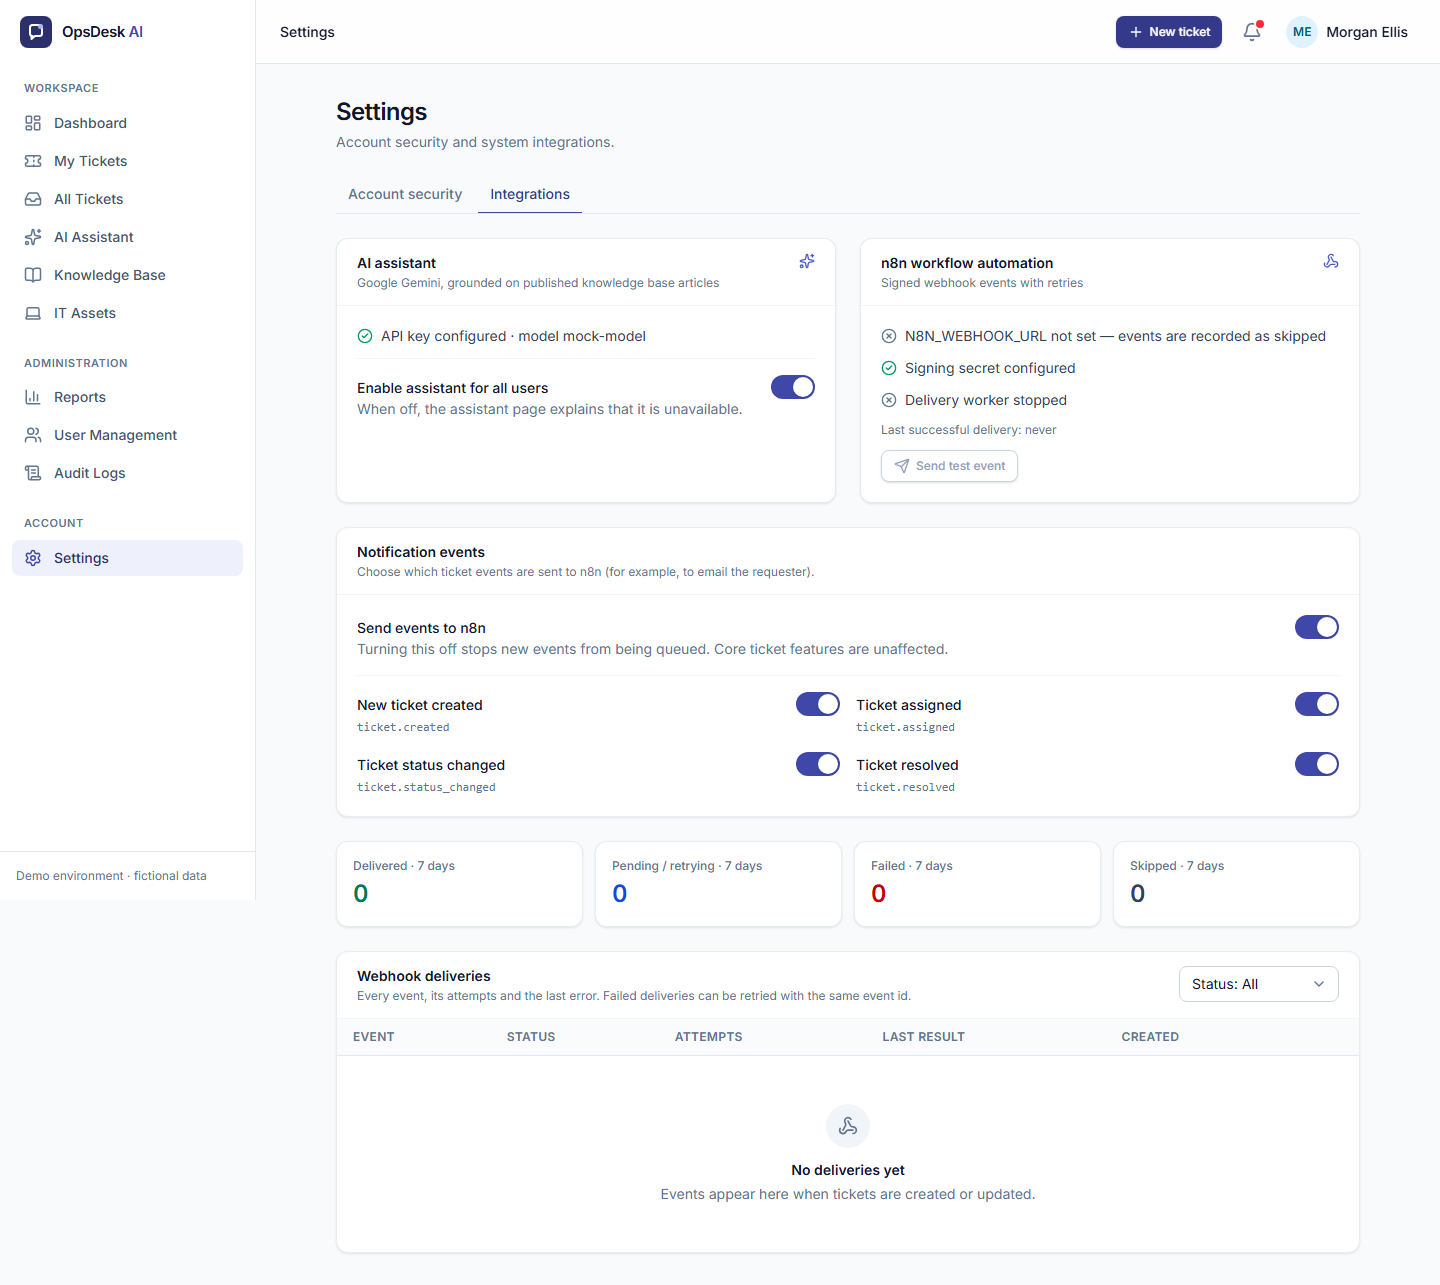
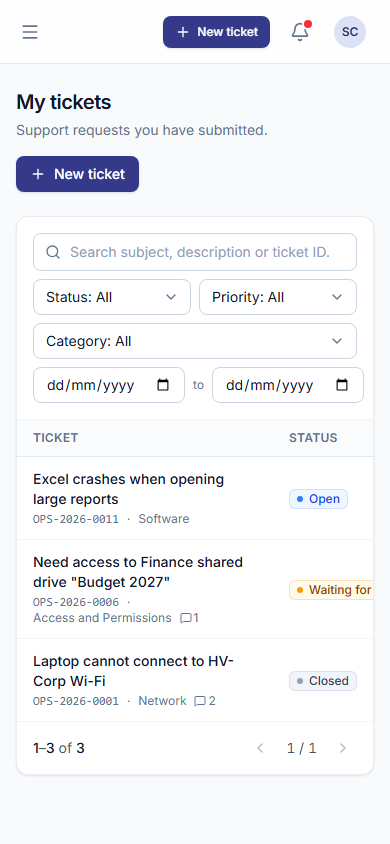
An IT help desk whose AI assistant answers only from published articles and cites them.
Read the case studyReact 19, Express 5, PostgreSQL 17, Gemini and n8n. 125 API tests and 28 end-to-end tests, all passing.
Run a pipeline from my projects and watch each step hand off to the next.
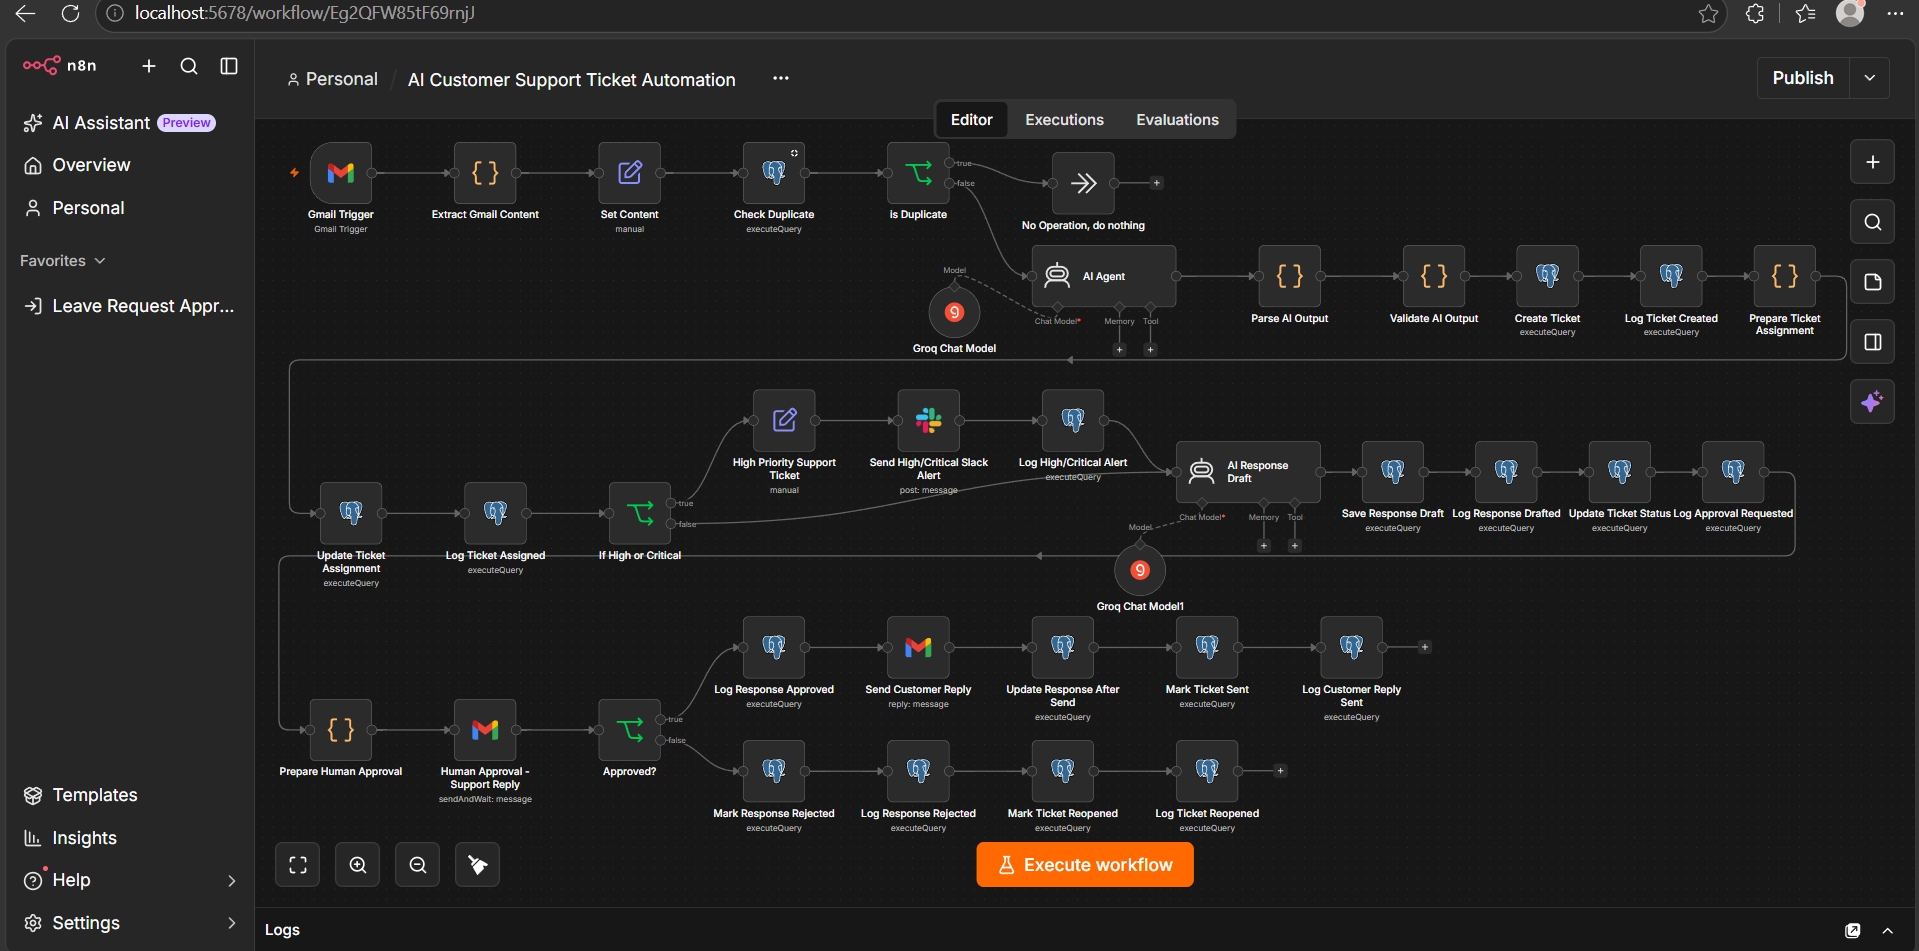
A customer email becomes a triaged, approved reply with an audit trail.
Ezekeil Third Cruz builds AI applications, Node.js back ends and n8n automations from the Philippines, and proves each one runs.
An IT help desk whose AI assistant answers only from published articles and cites them.
Read the case studyReact 19, Express 5, PostgreSQL 17, Gemini and n8n. 125 API tests and 28 end-to-end tests, all passing.
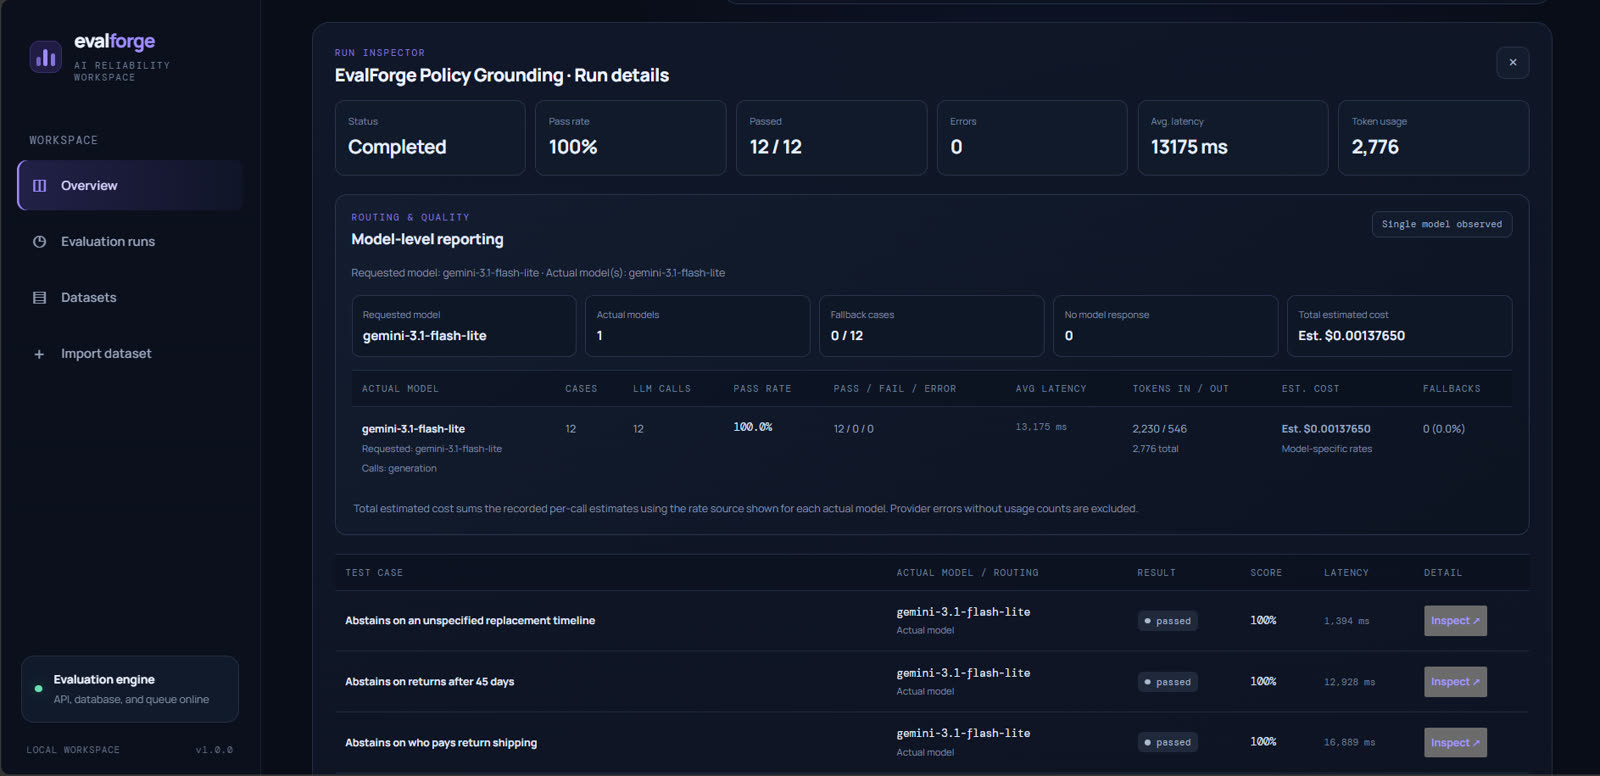
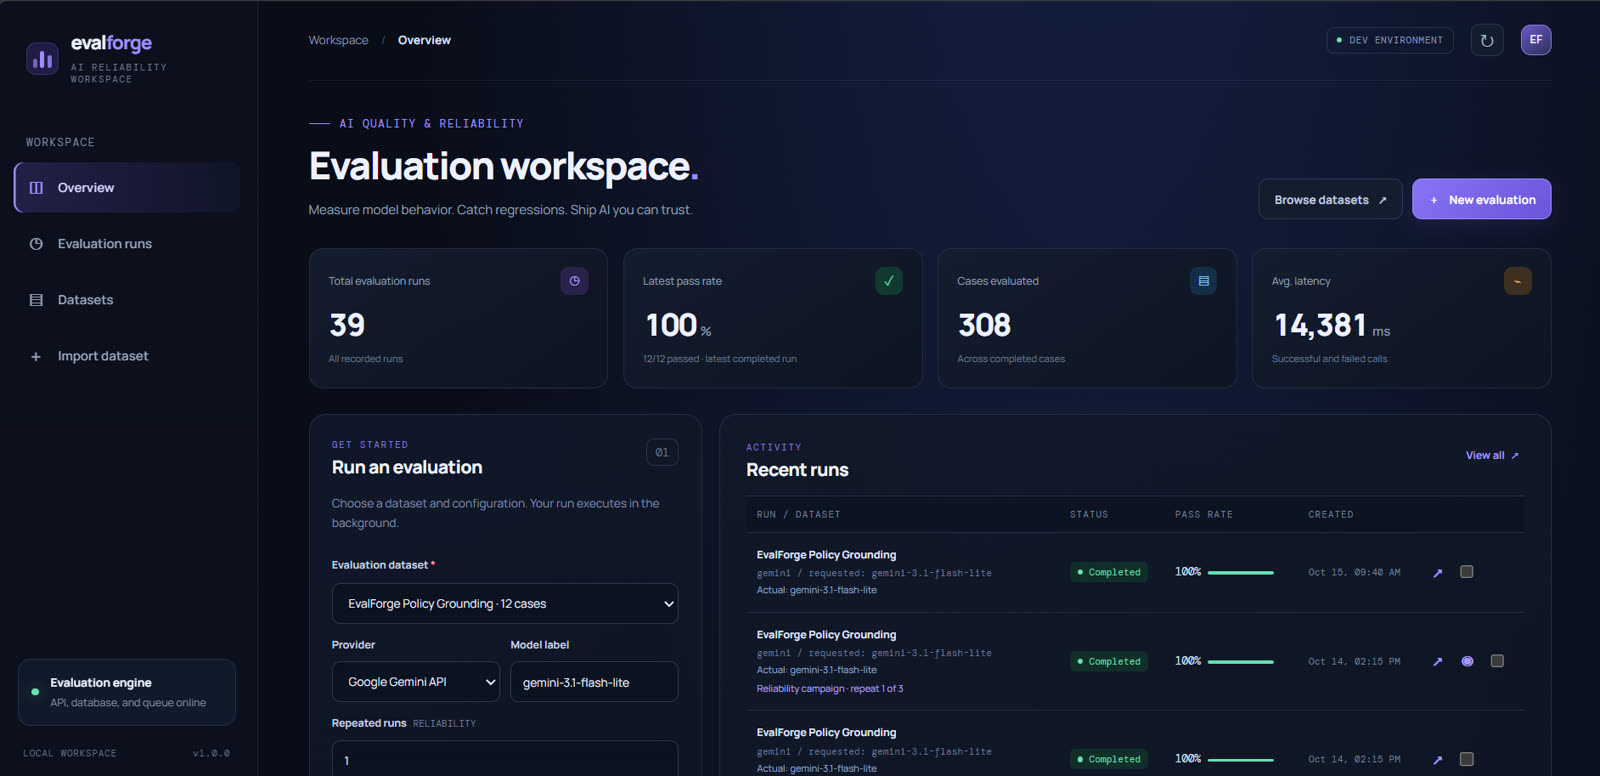
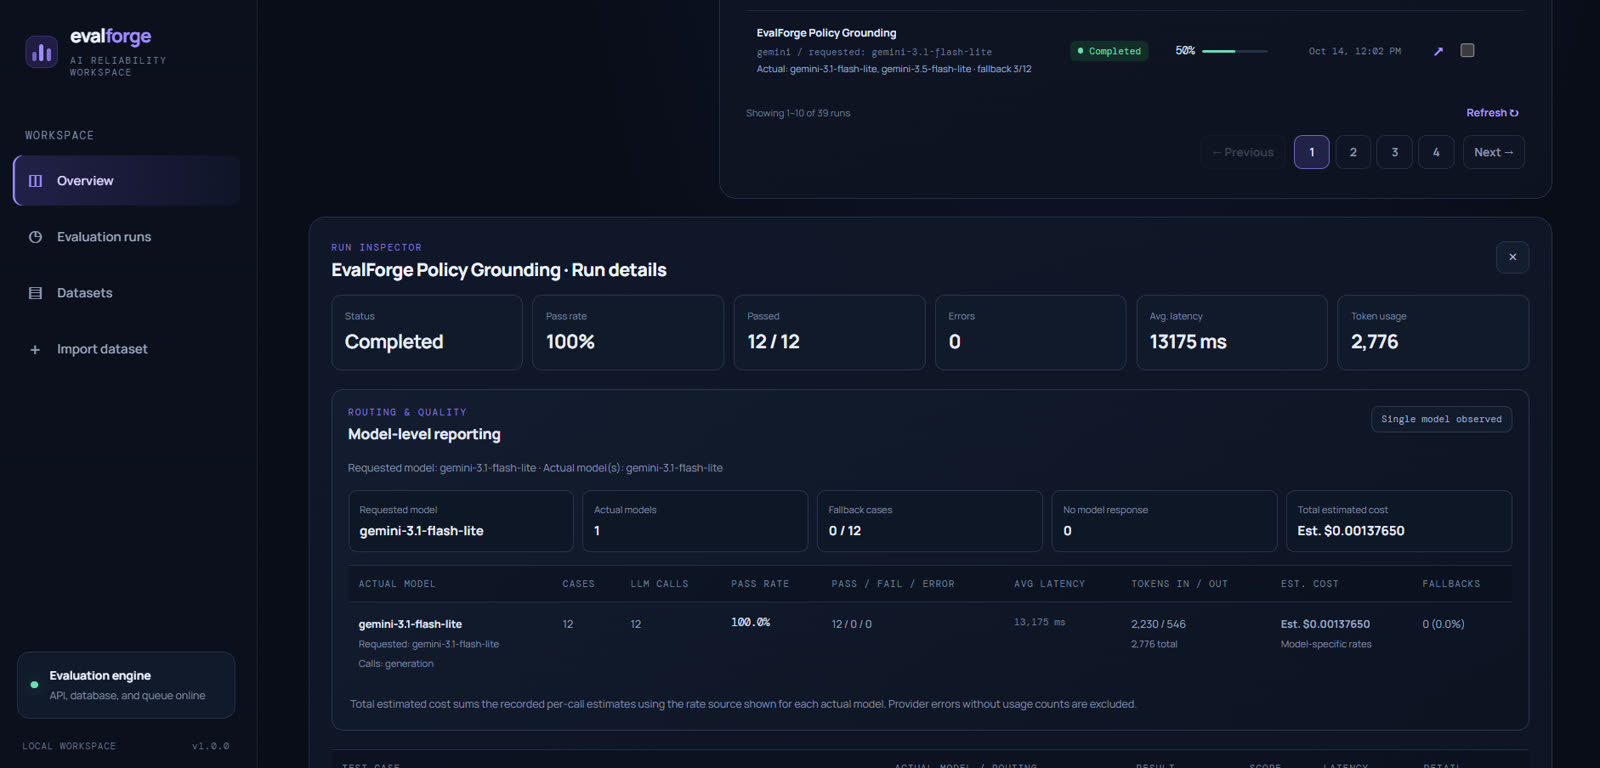
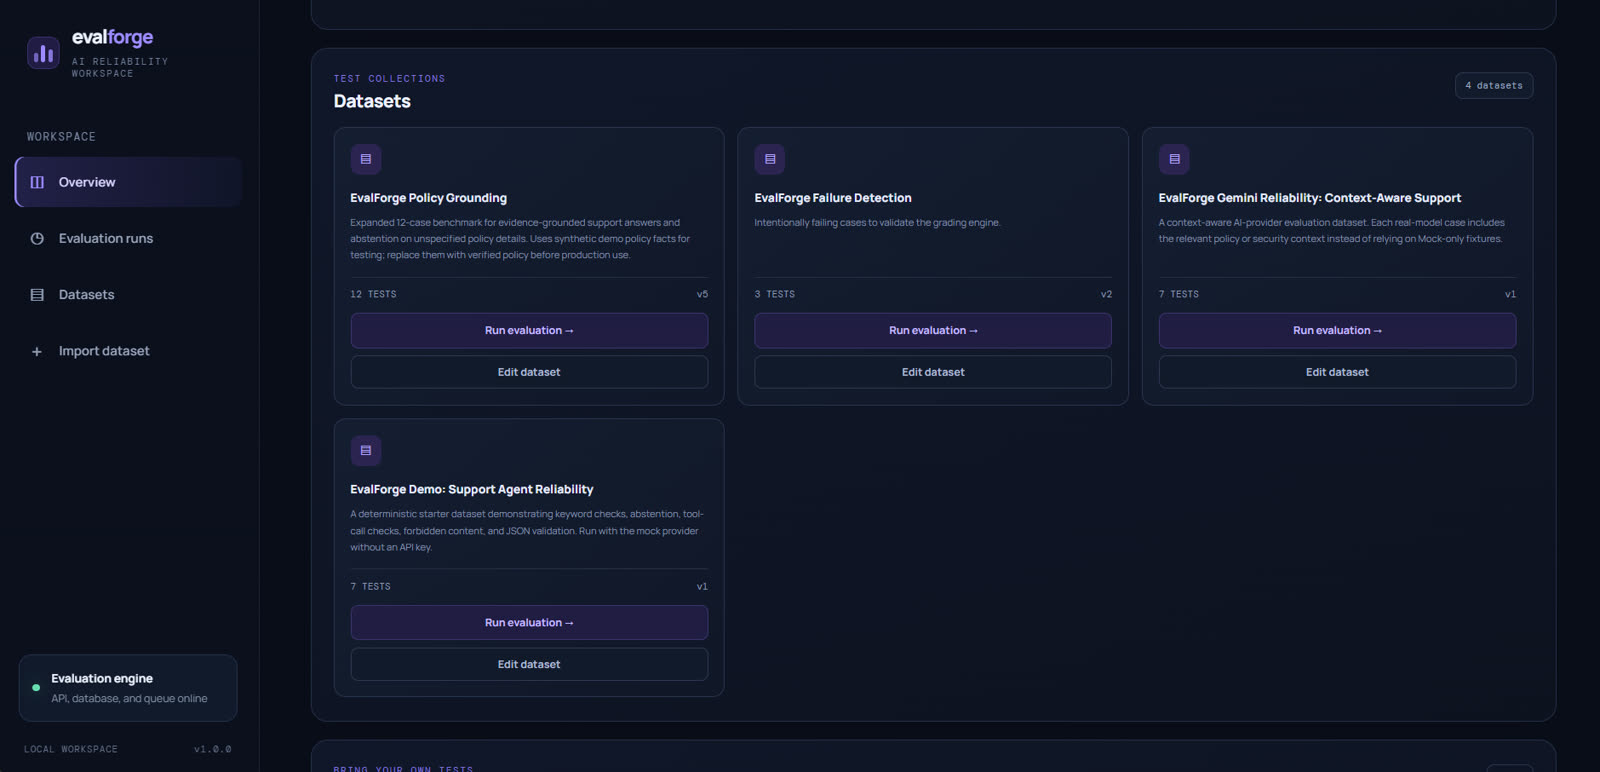
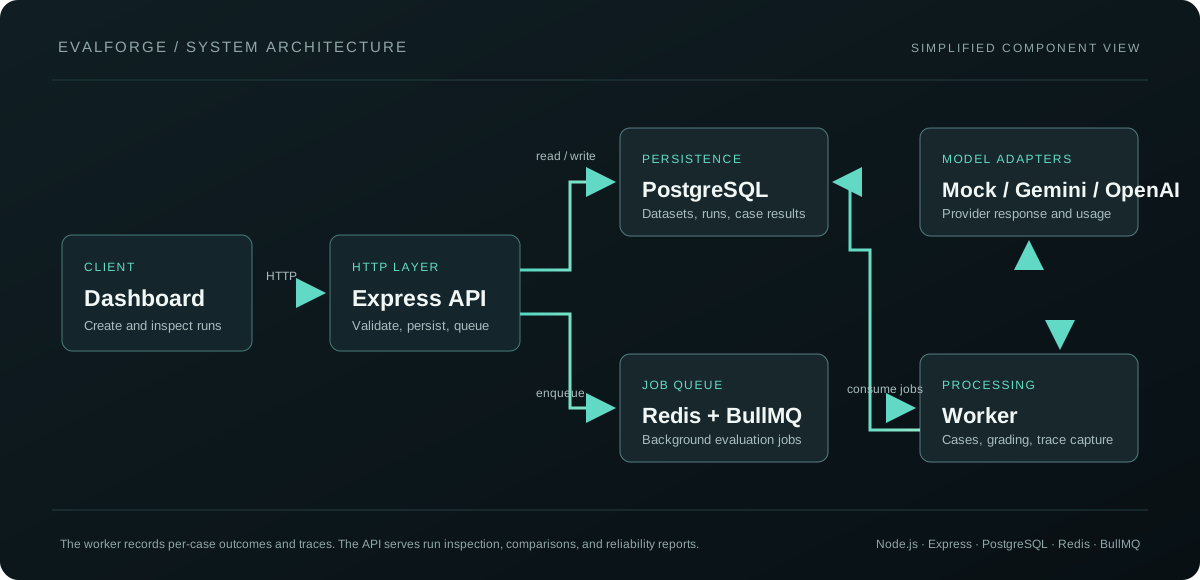
Queued model evaluations you can compare run against run, so a regression shows up as a number.
Read the case studyExpress, Redis and BullMQ workers, PostgreSQL, and Mock, Gemini or OpenAI adapters.
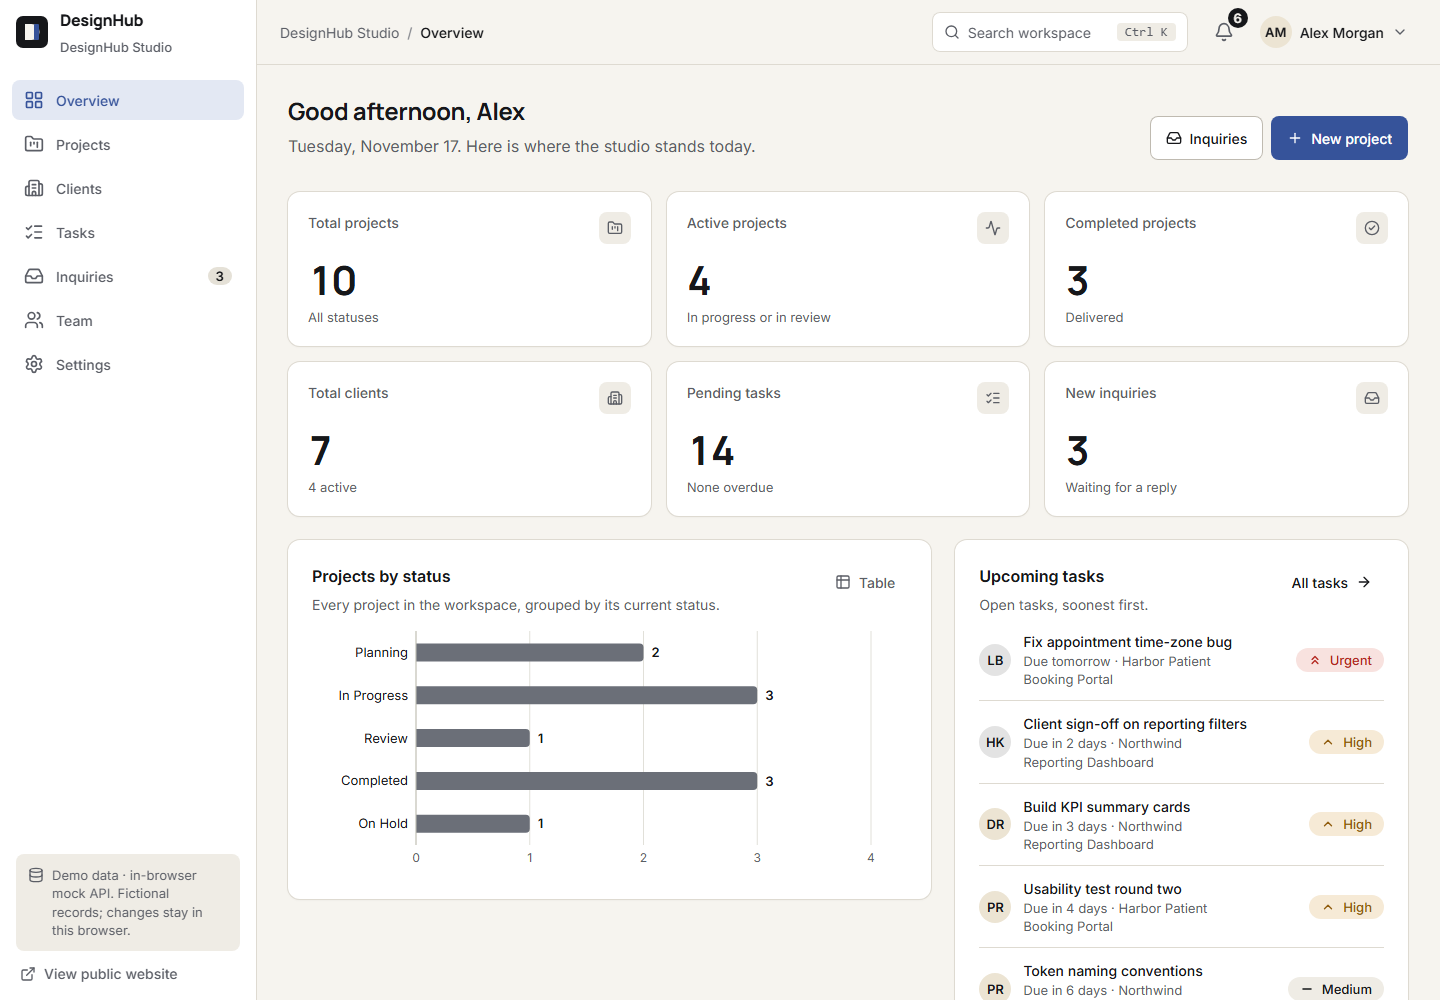
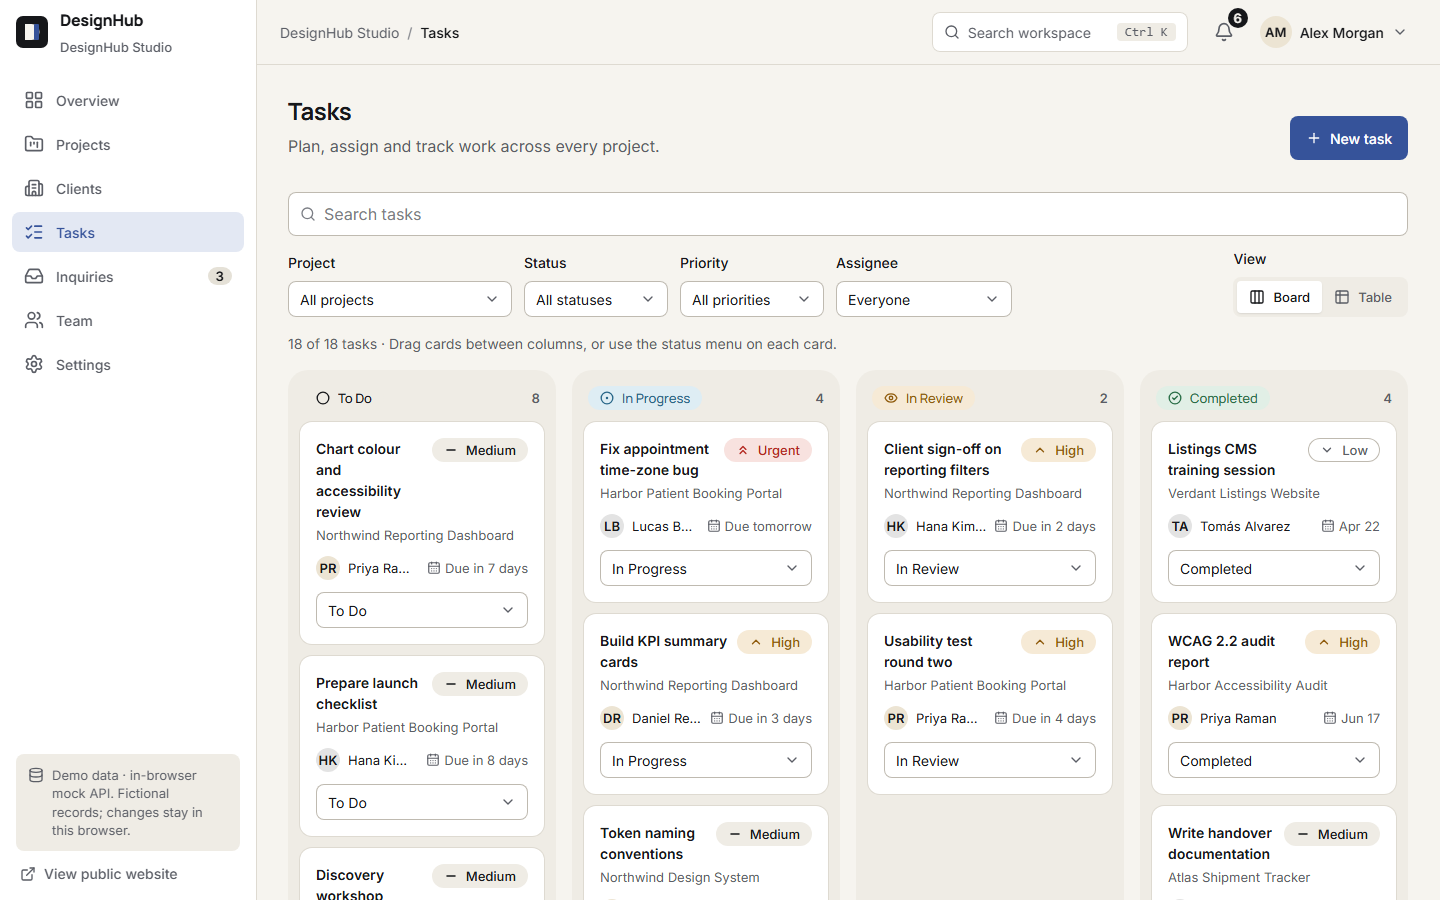
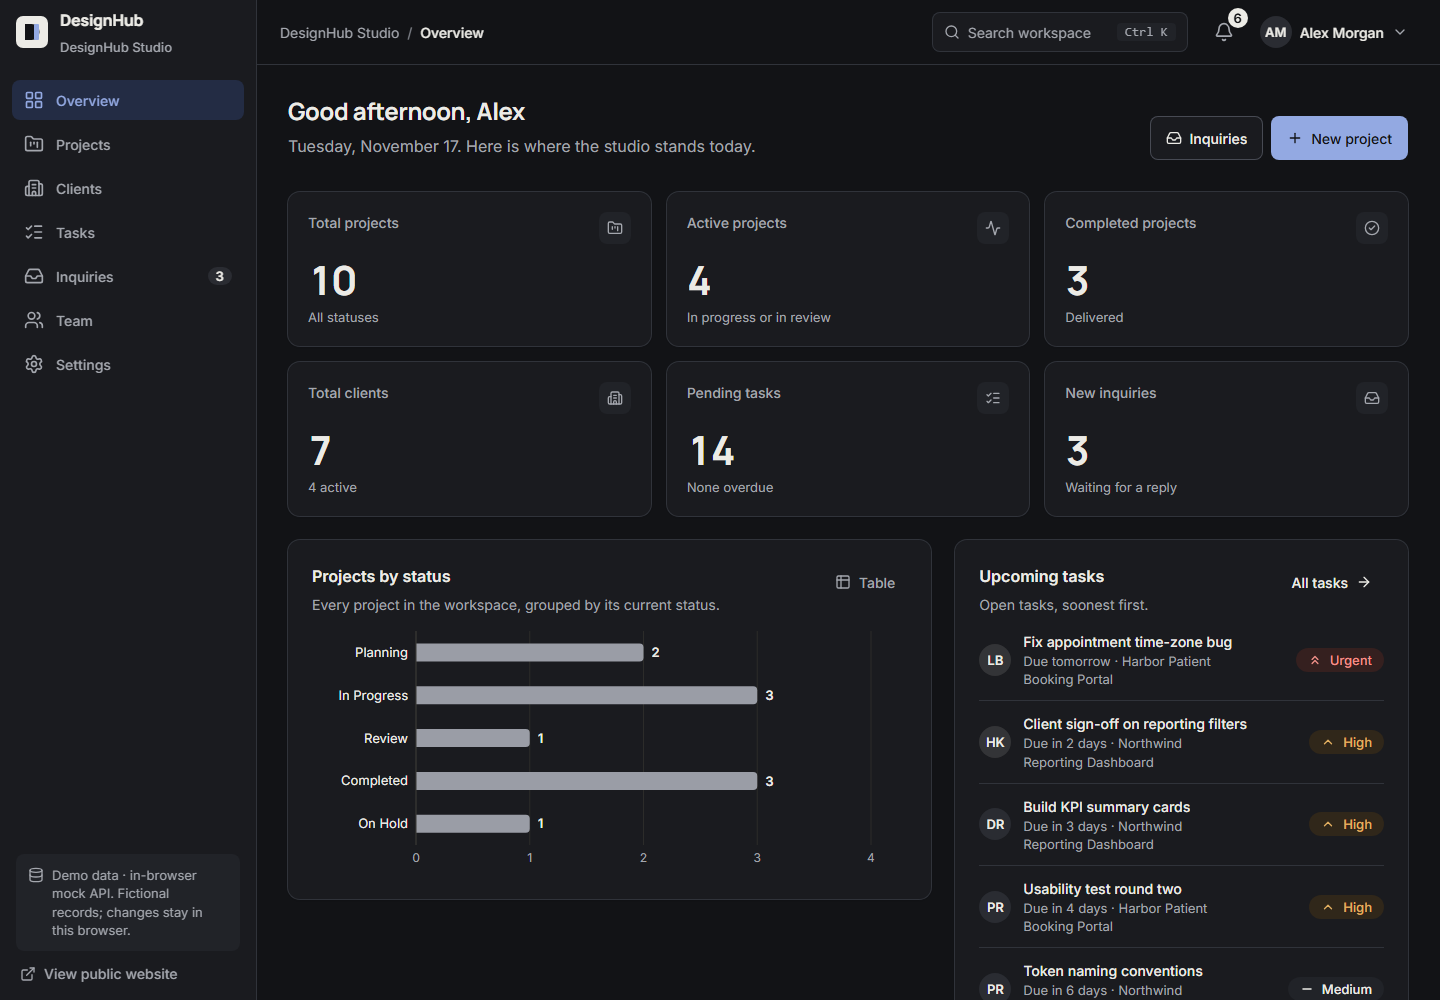
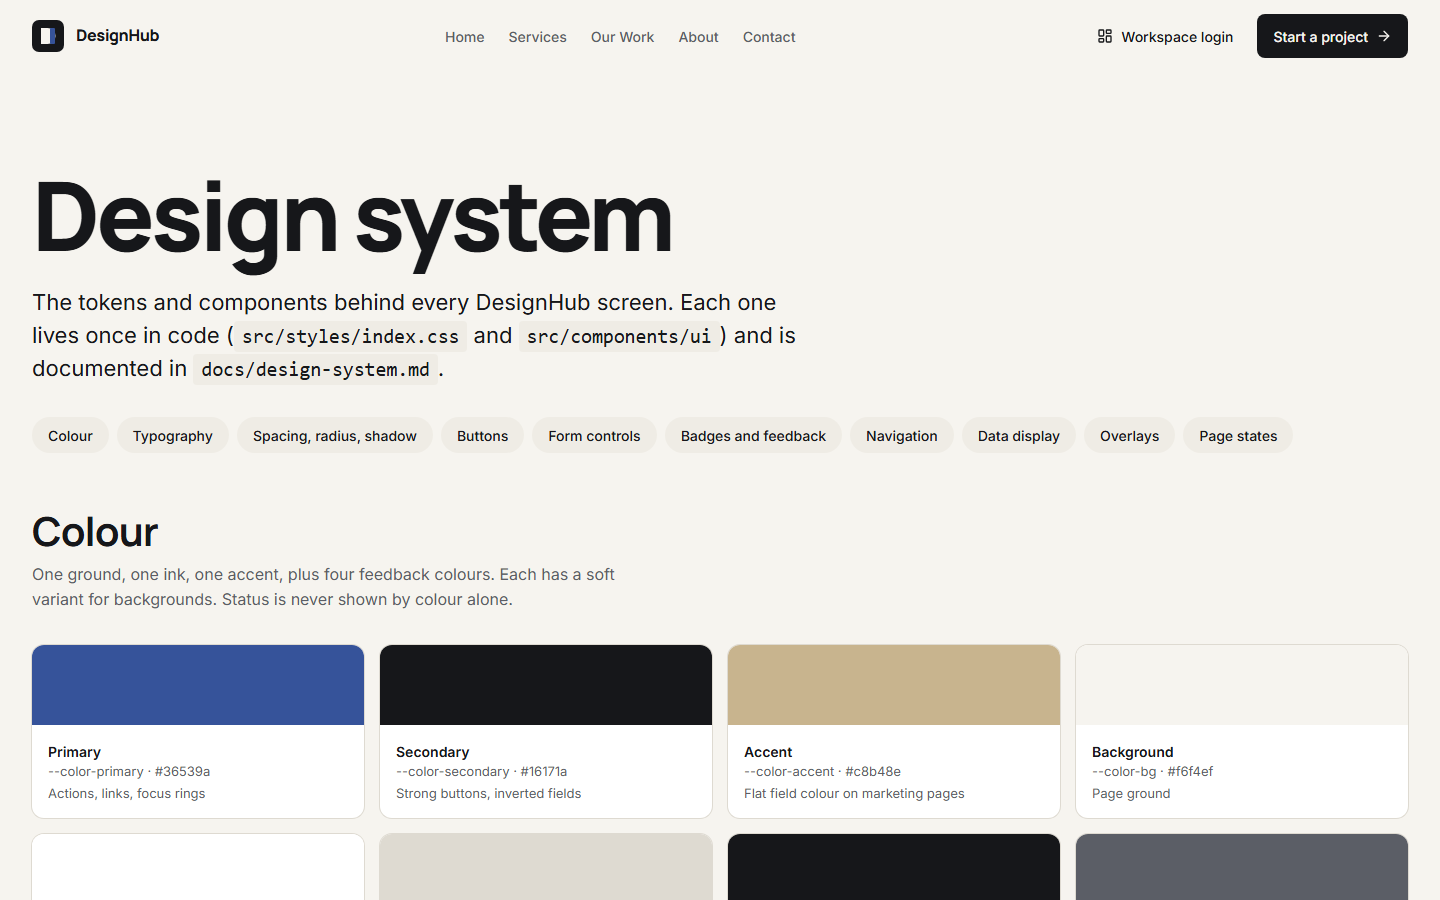
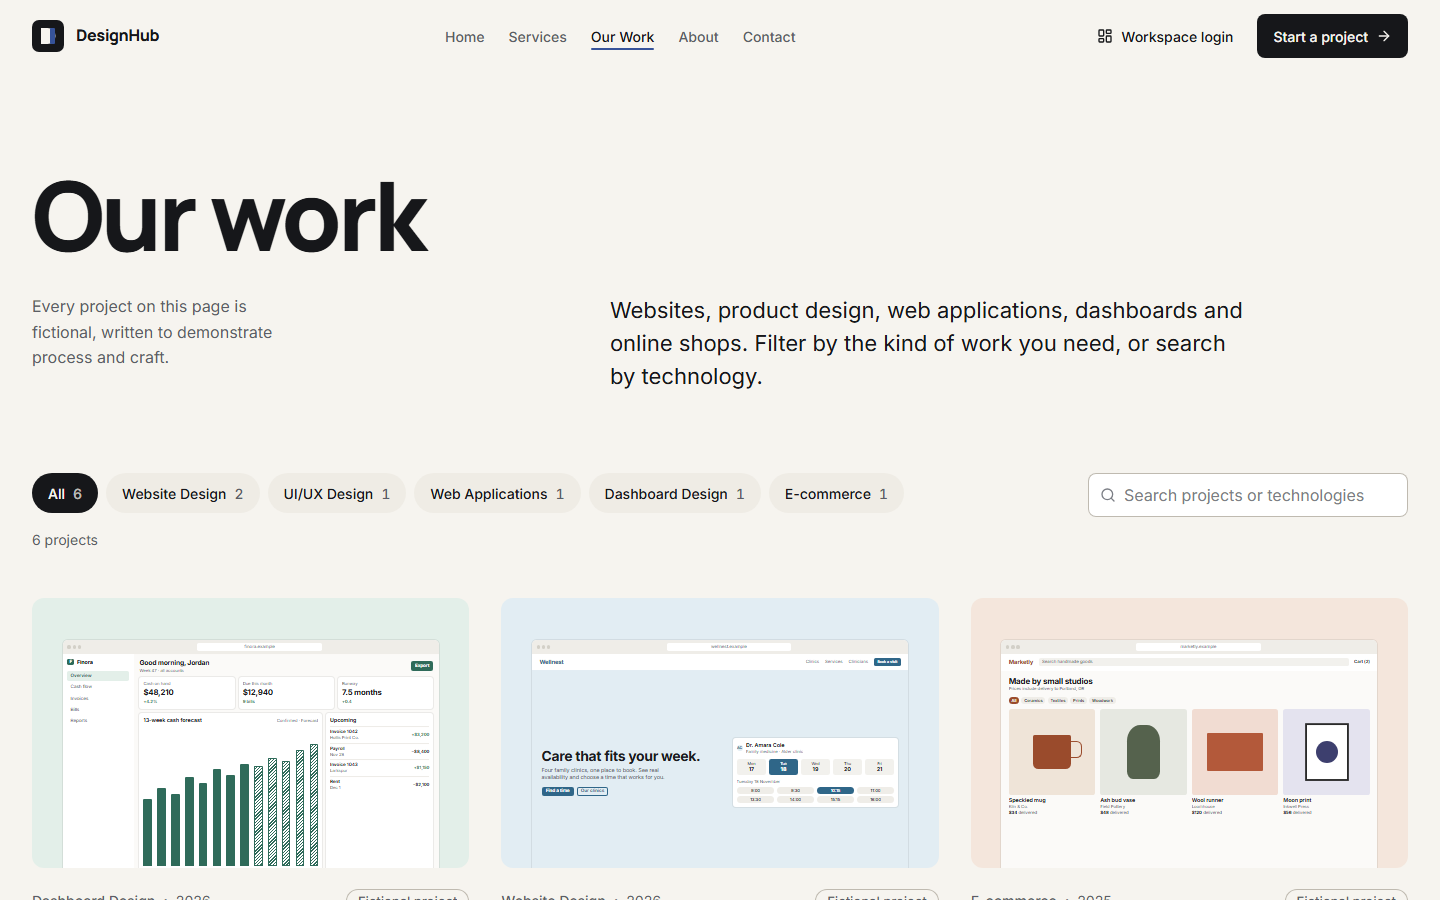
A studio website and project workspace built on one token file, with 29 components and both themes.
Read the case studyReact 19, Tailwind CSS 4, Express and Zod. 84 Playwright tests, 20 API tests, 0 axe violations.
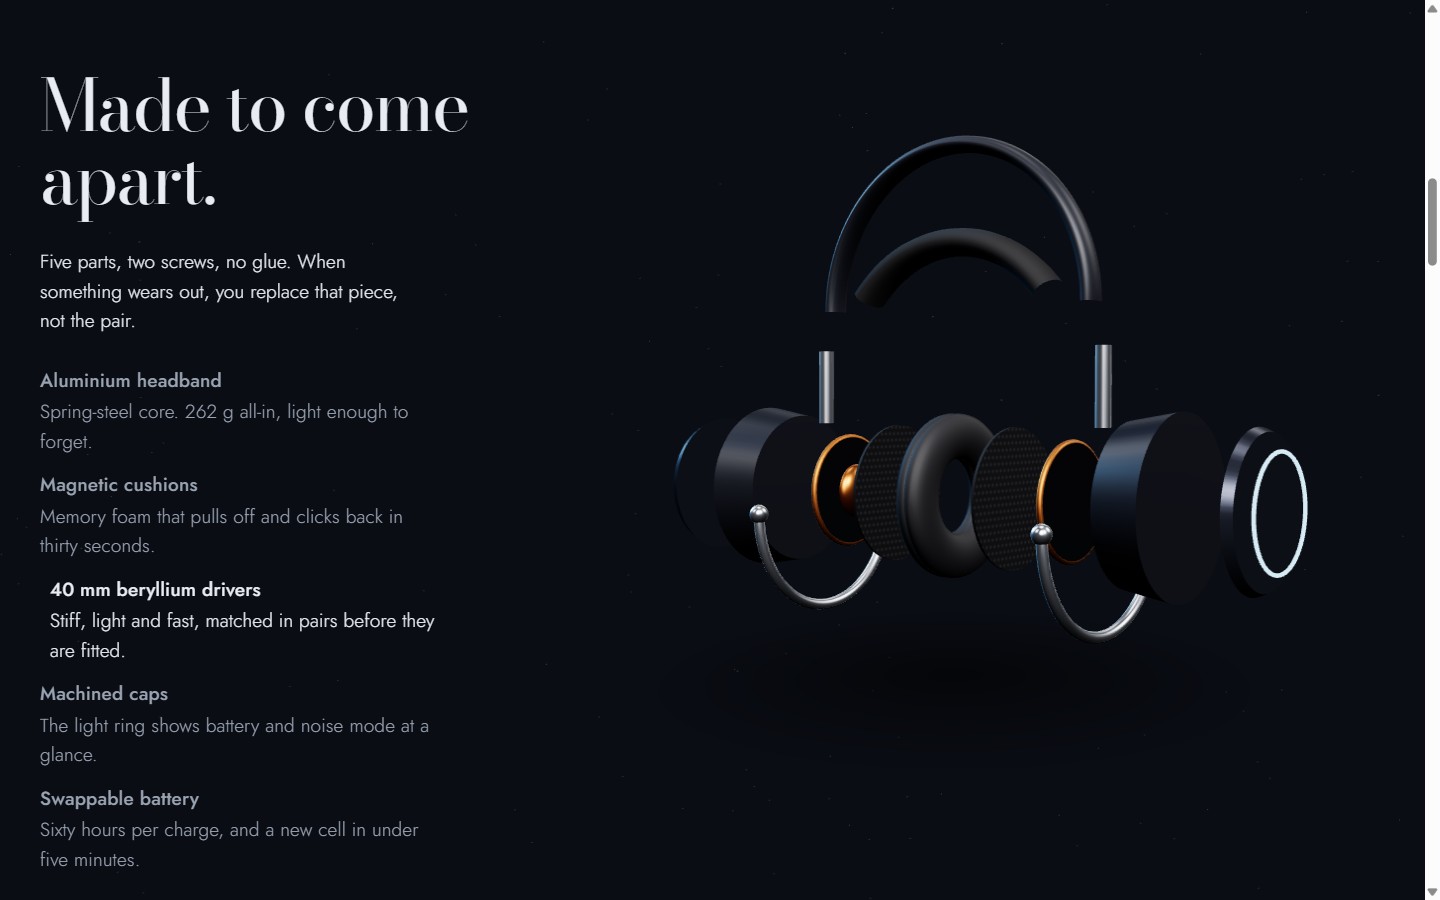
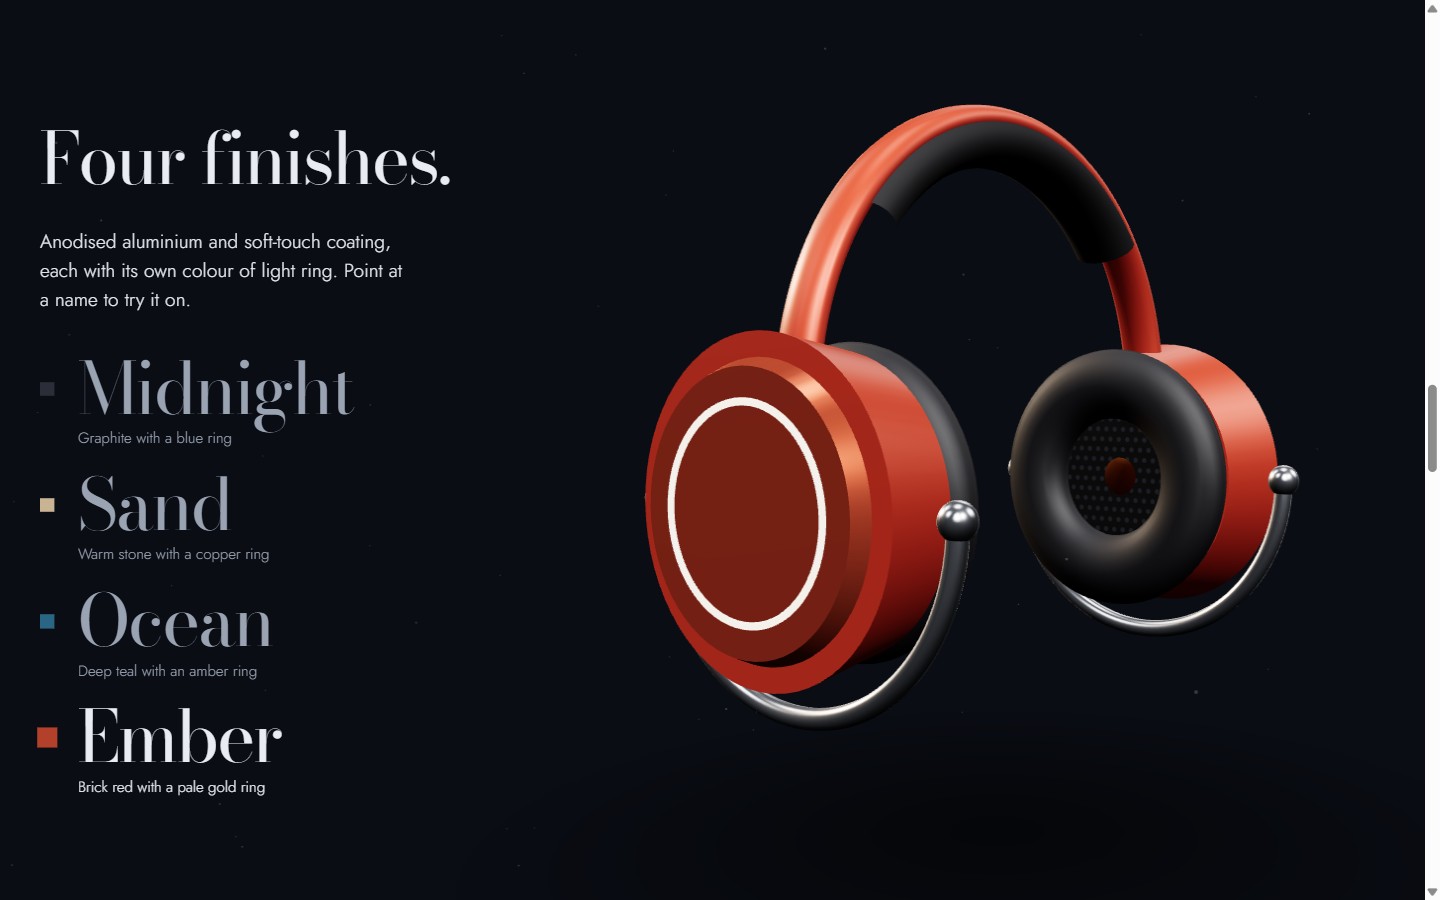
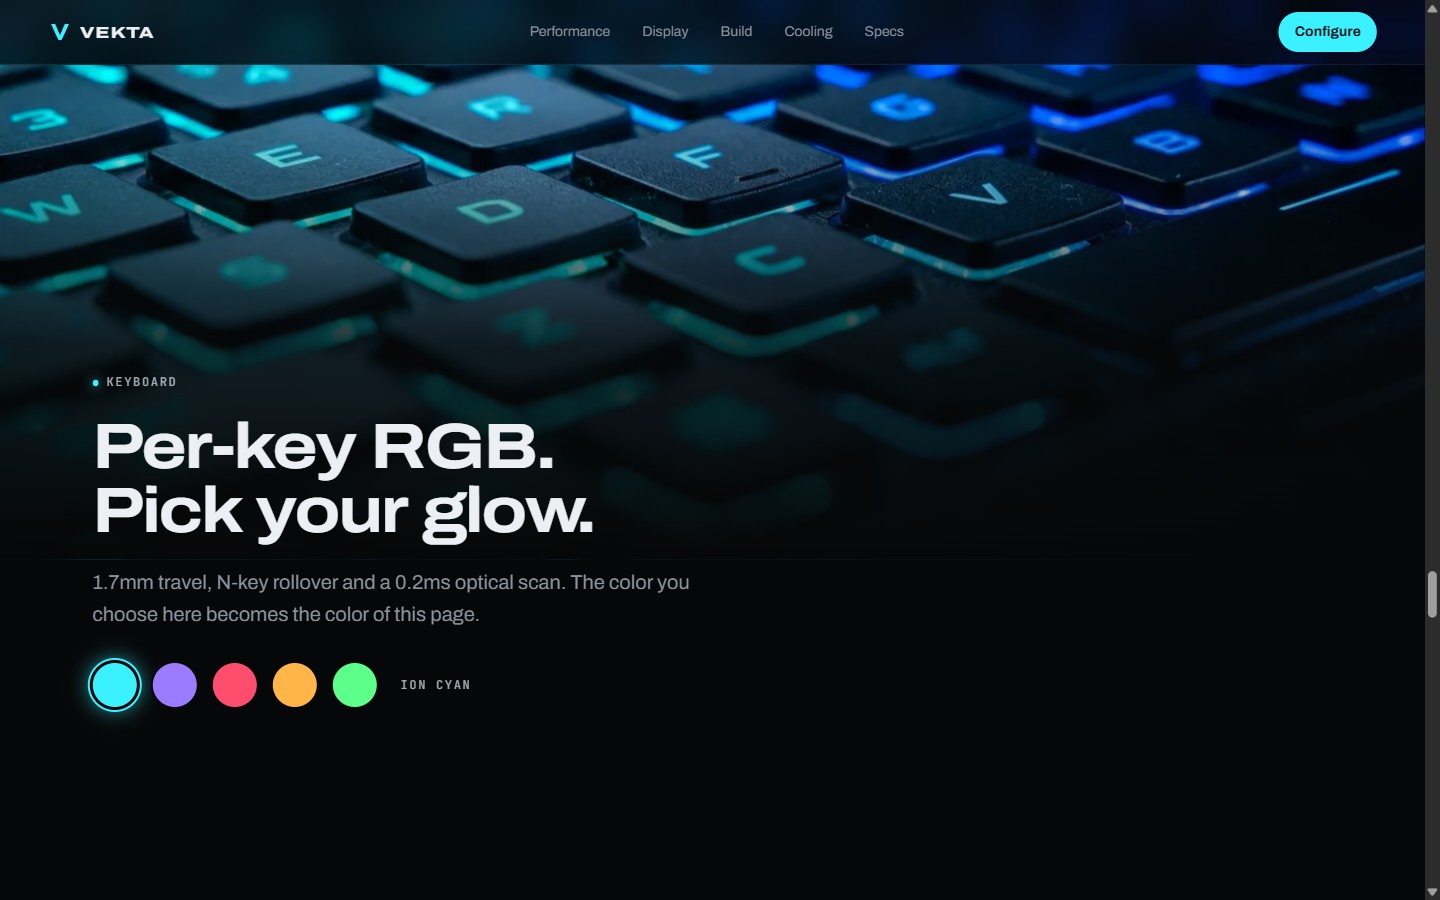
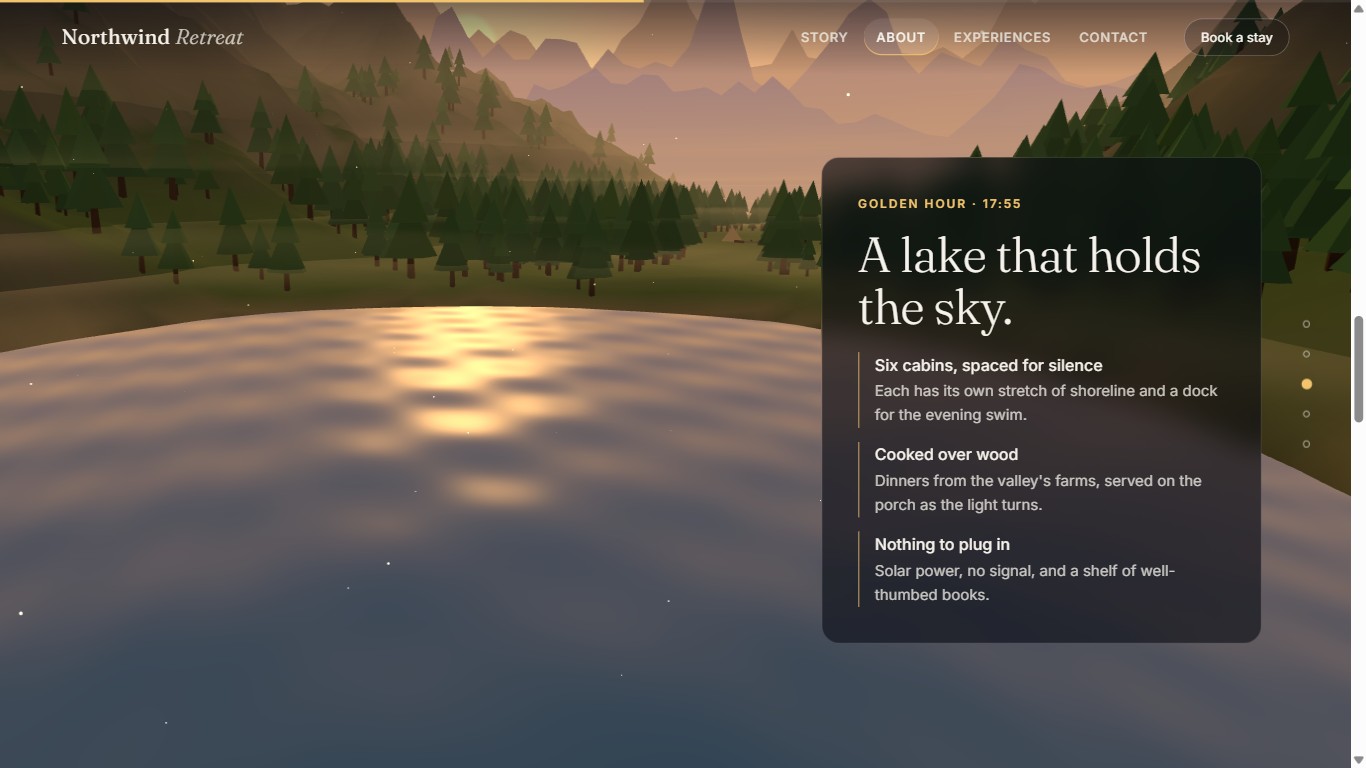
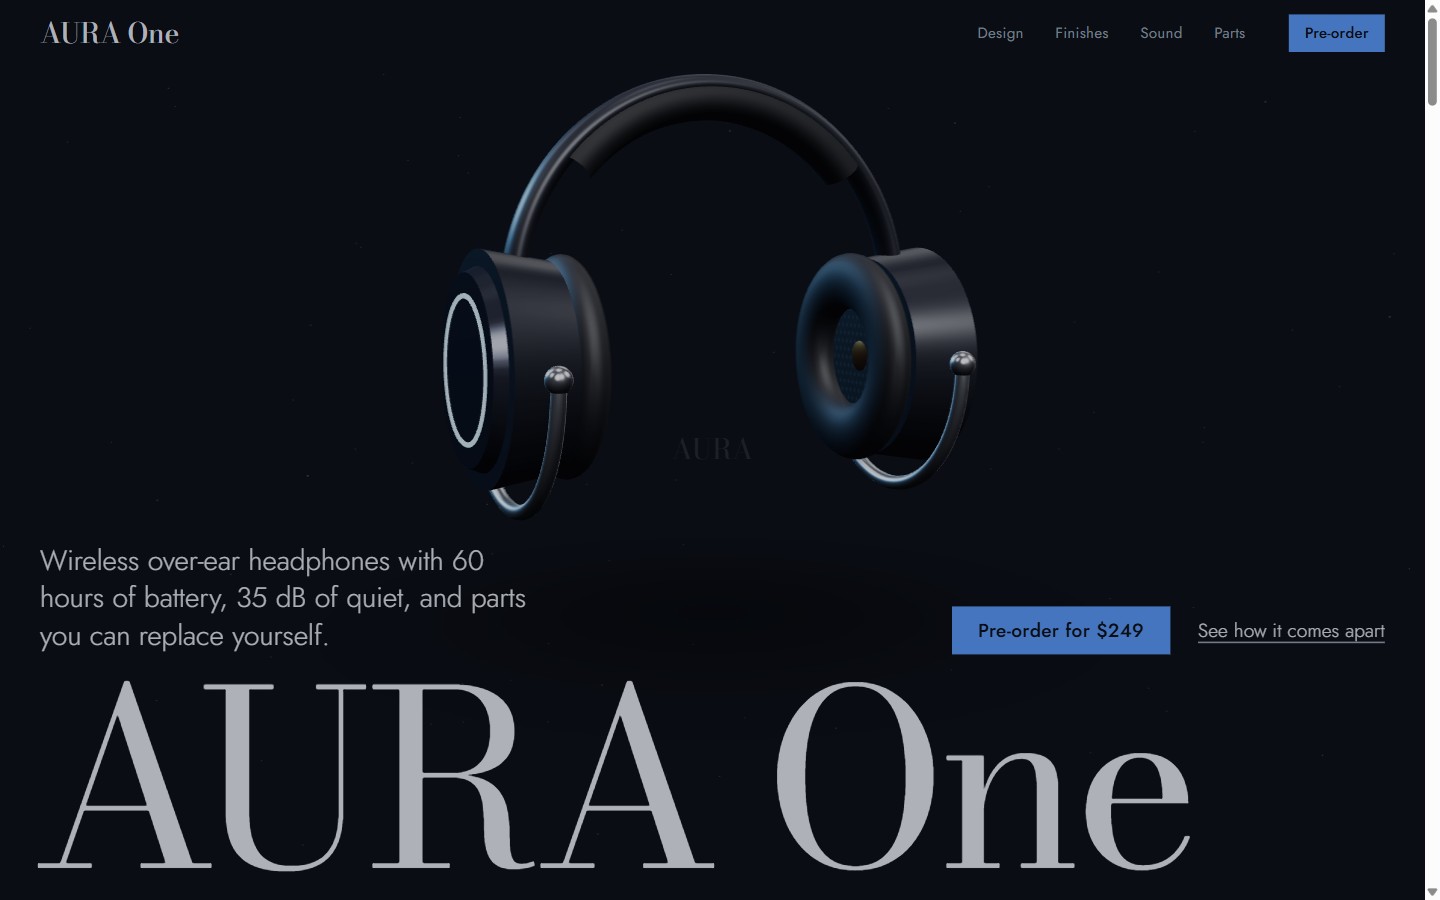
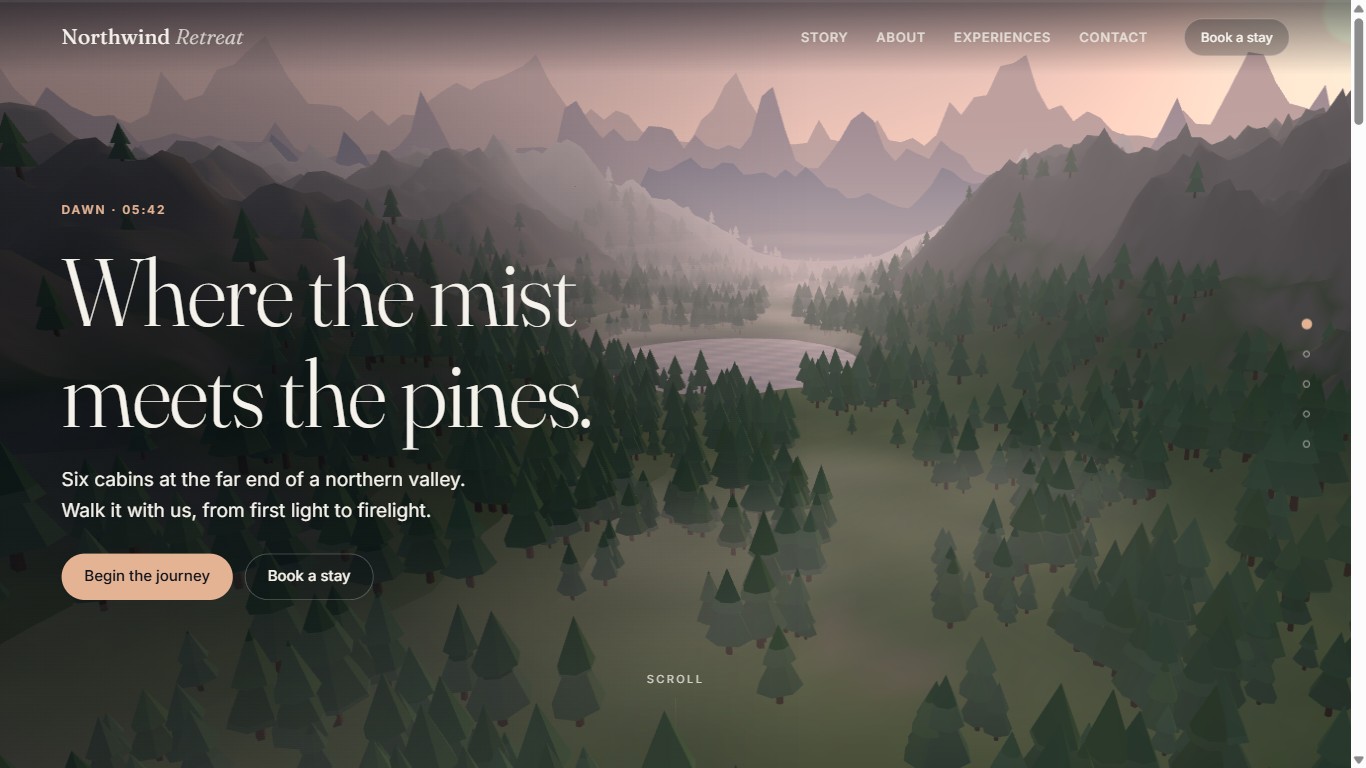
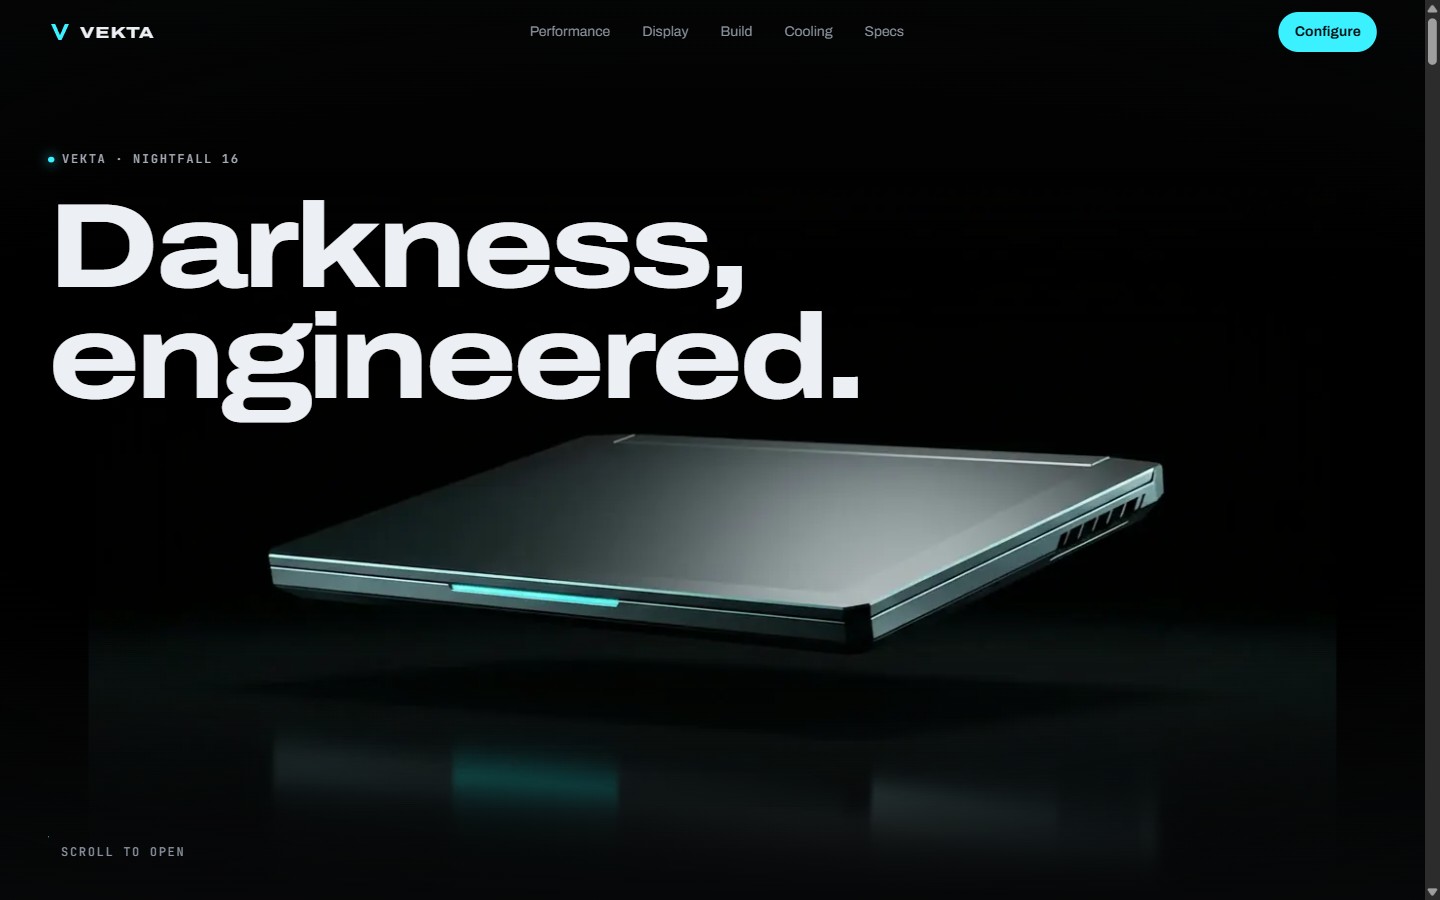
Product pages that move with the scroll: headphones built from code, a laptop scrubbed frame by frame, and a valley from dawn to night.
AURA One VEKTA Nightfall 16 Landscape Journeythree.js, GSAP ScrollTrigger, Lenis and custom shaders. All three brands are fictional.
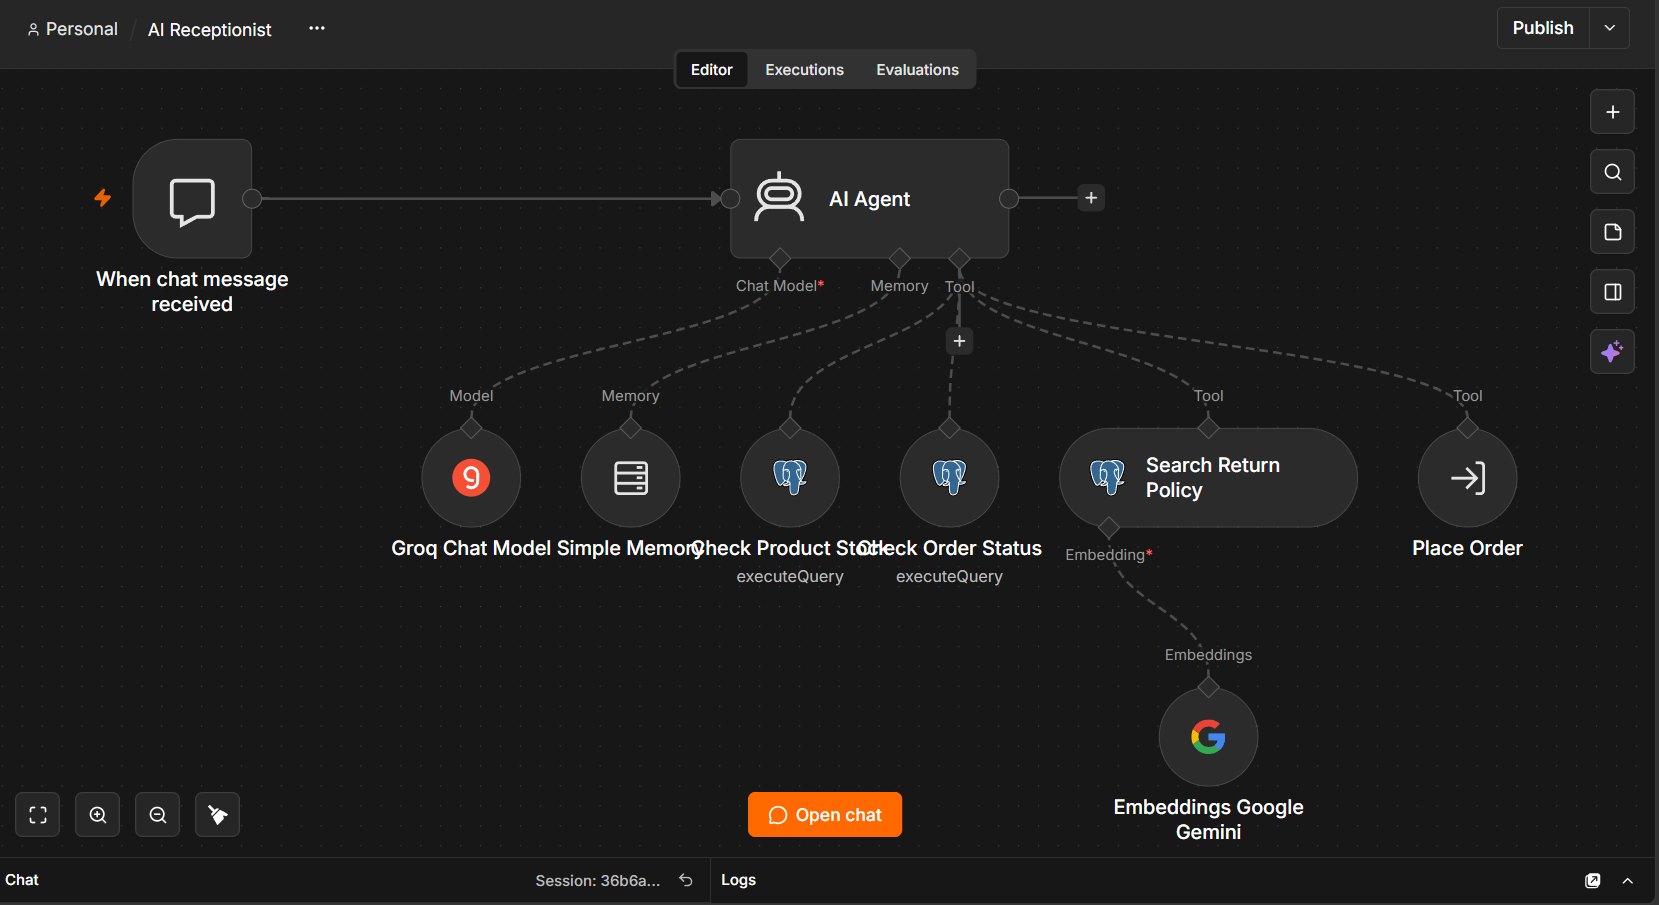
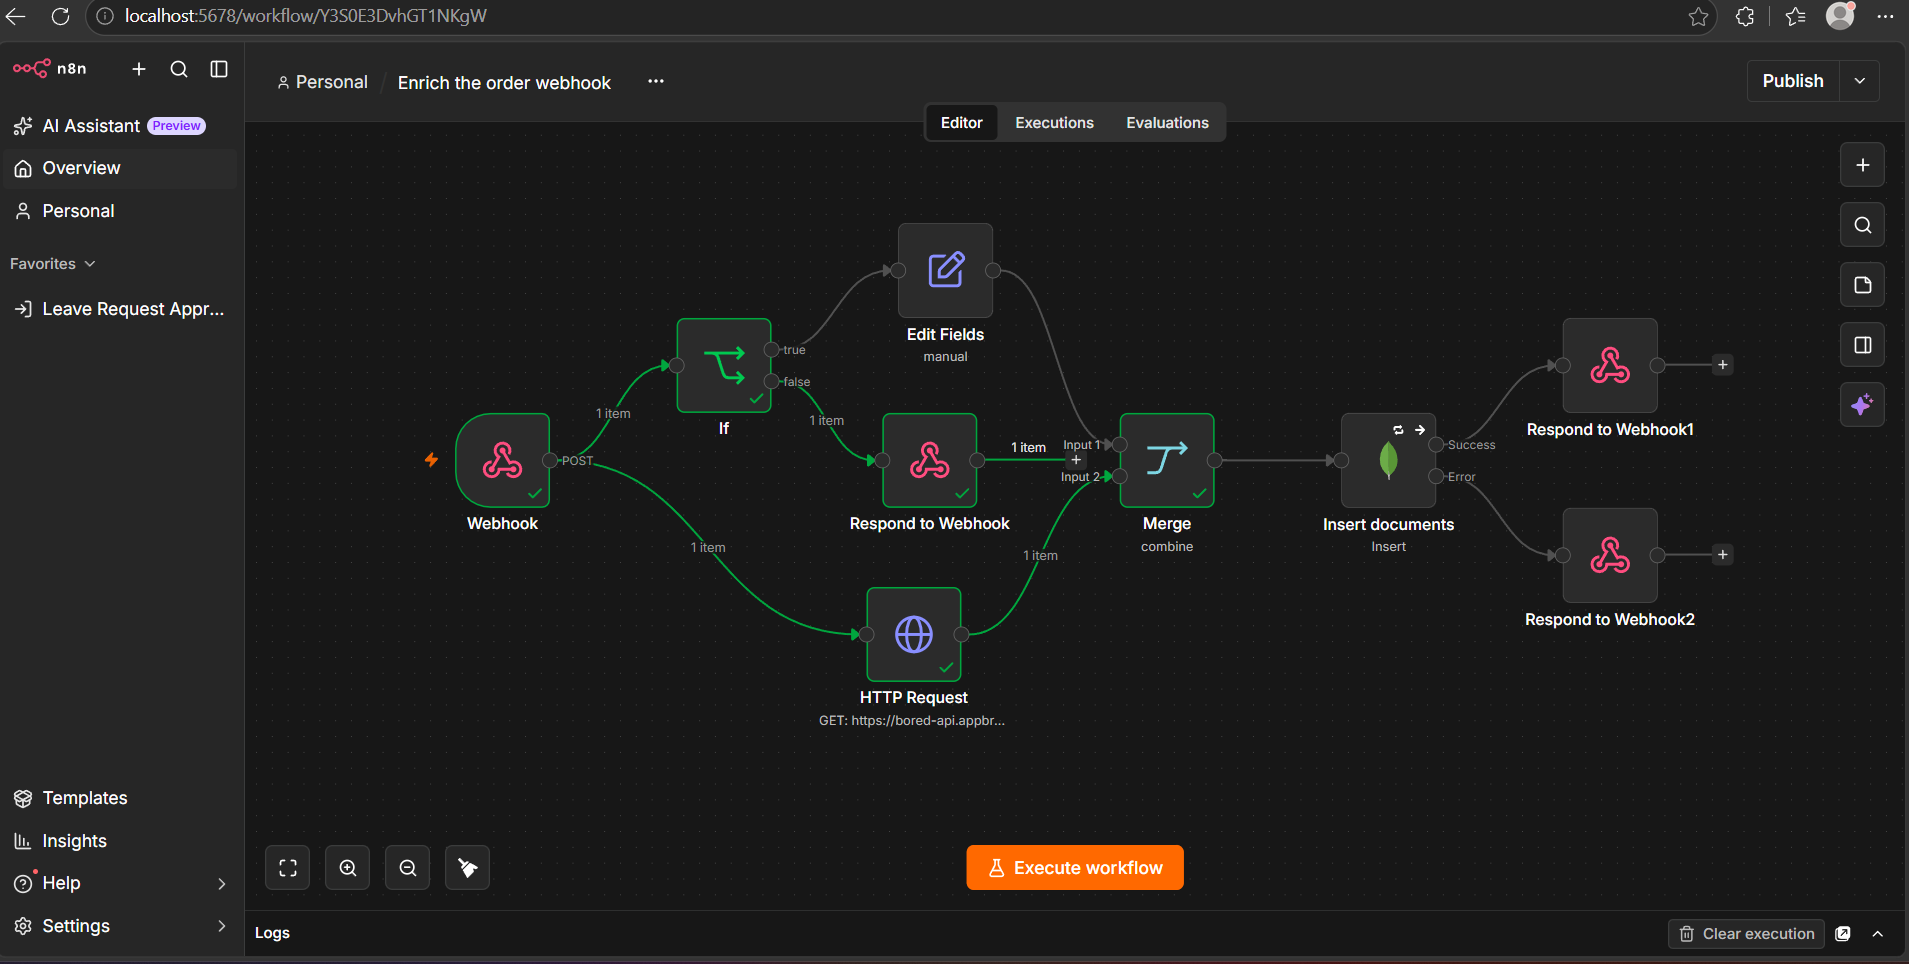
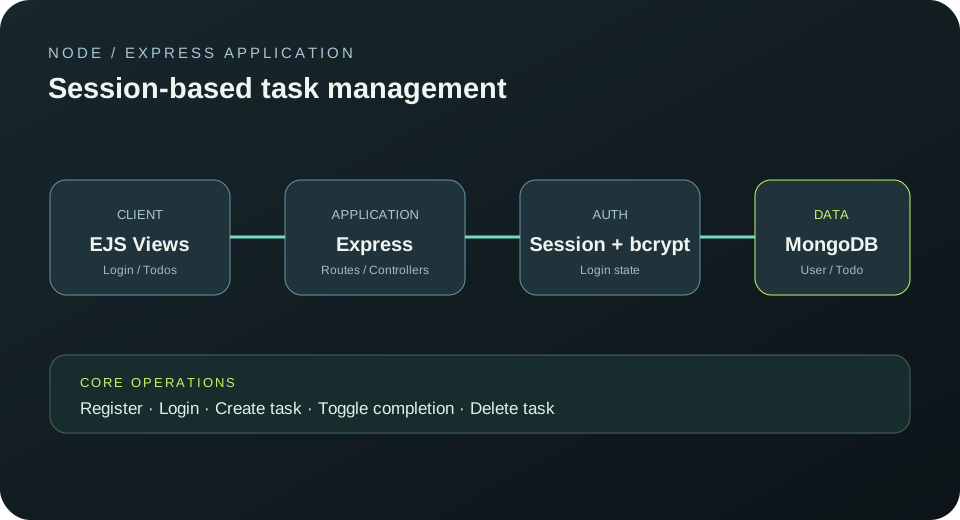
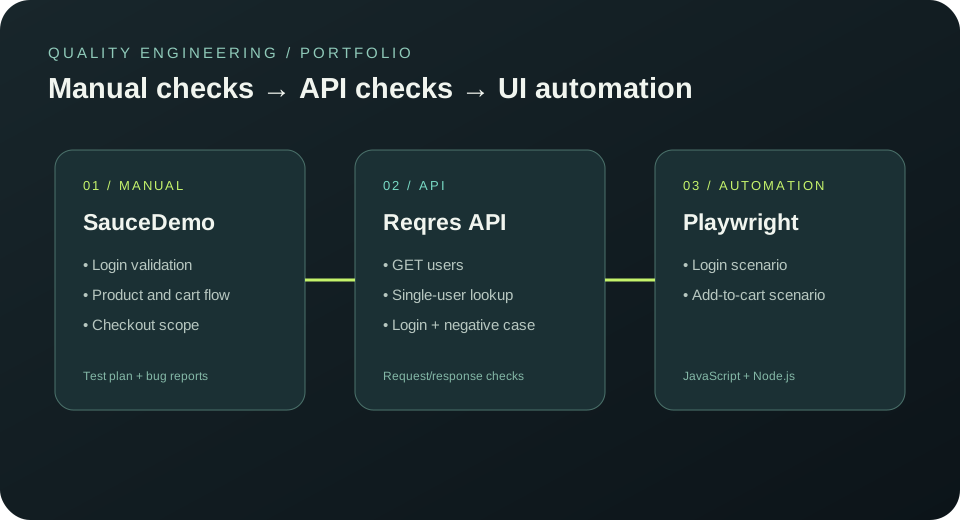
Fourteen projects, each with a case study that lists what was tested and what is still missing.
| Project | Check | Tool | Result |
|---|---|---|---|
| OpsDesk AI | API tests | Node test runner, Supertest | 125 passing |
| End-to-end tests | Playwright | 28 passing | |
| WCAG 2.1 AA scan | axe | 0 violations | |
| Live checks against the model | Gemini API | 11 passing | |
| DesignHub | Browser suites | Playwright | 84 tests |
| API tests | node:test, Supertest | 20 tests | |
| Defects found by the suites | Testing report | 16 fixed | |
| Accessibility, light and dark | axe | 0 violations | |
| QA Portfolio | UI scenarios, login and cart | Playwright | 8 cases |
| Support Automation | Normal, urgent, duplicate and error paths | n8n executions | Screenshots kept |
Counts come from each repository's README and testing notes. Nothing here is rounded up.
First, a customer writes in.
Charged twice for order 4471
Hi, my card was charged twice for the same order yesterday. Can you refund one of them?
{
  "category": "billing",
  "priority": "high",
  "sentiment": "negative",
  "needs_human_review": true
}
The model classifies it into structured fields. Sample message, fields simplified.
Then, the server checks the model.
if (!ALLOWED.priority.includes(out.priority)) {
  return sendToReview(ticket);
}
const team = TEAM_BY_CATEGORY[out.category];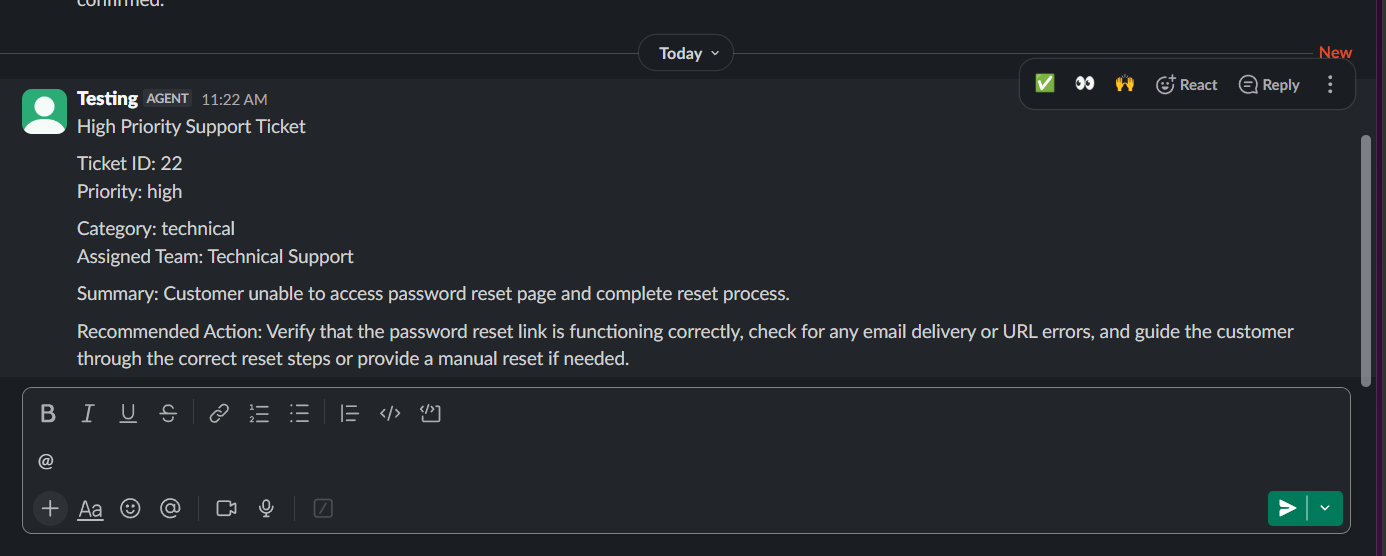
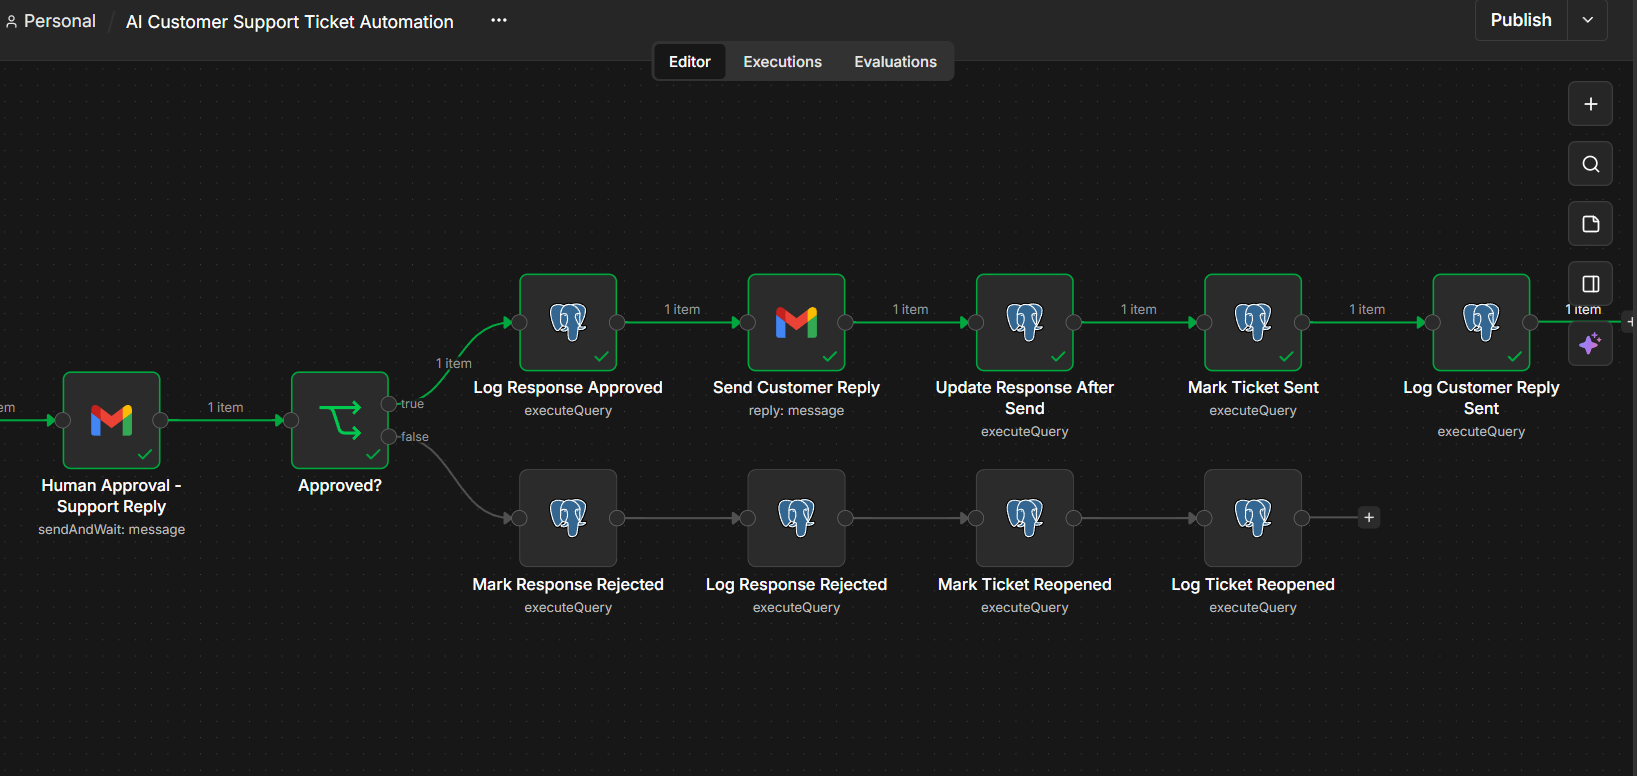
Finally, a person approves the reply.
Hi, thanks for flagging this. I can see two charges for order 4471 and have asked our billing team to refund the duplicate.
I work from the process outward: find the trigger, shape the data, decide which system owns each step, then test what actually runs.
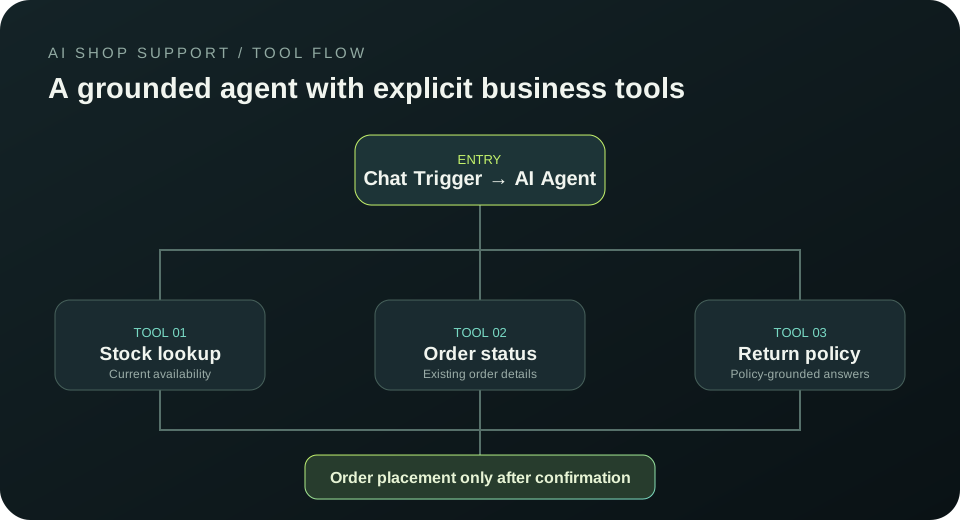
Lately that means AI with guardrails: retrieval that cites its sources, evaluation runs that can be compared side by side, and approval steps that keep a person in charge of what gets sent. I am looking for a team where that kind of care is normal.
Stack